# Mastering Prosody Modeling in AI Voiceovers: A Comprehensive Guide for Video Producers

Published: July 2, 2025 · Author: Hitesh Kumawat

Prosody modeling is how an AI voice predicts the rhythm, stress, pitch and pauses of a sentence. It's the main reason one voice sounds natural and another sounds robotic, even when both say every word correctly. As a video producer, you shape it through your script, punctuation, speed and pitch settings, emotion settings and, in some tools, SSML.

*Last updated: October 6, 2026. We checked the research paper and the W3C specification cited below on that date.*

This guide is for video producers, course creators and marketers who want to understand why AI voiceovers sound the way they do, and how to steer them. It starts with plain definitions, then covers how models work and what you can control.

> **Key Takeaways**
>
> - **Prosody is the music of speech:** rhythm, stress, intonation and pauses. It carries meaning and emotion beyond the words.
> - **Prosody modeling decides naturalness.** Poor prosody is the most common reason an AI voice sounds flat or robotic.
> - **Modern models predict pitch, duration and energy** from text. FastSpeech 2 is a well-known example from 2020 research.
> - **You control prosody in 4 ways:** script and punctuation, global settings, emotion settings or styles, and SSML where supported.
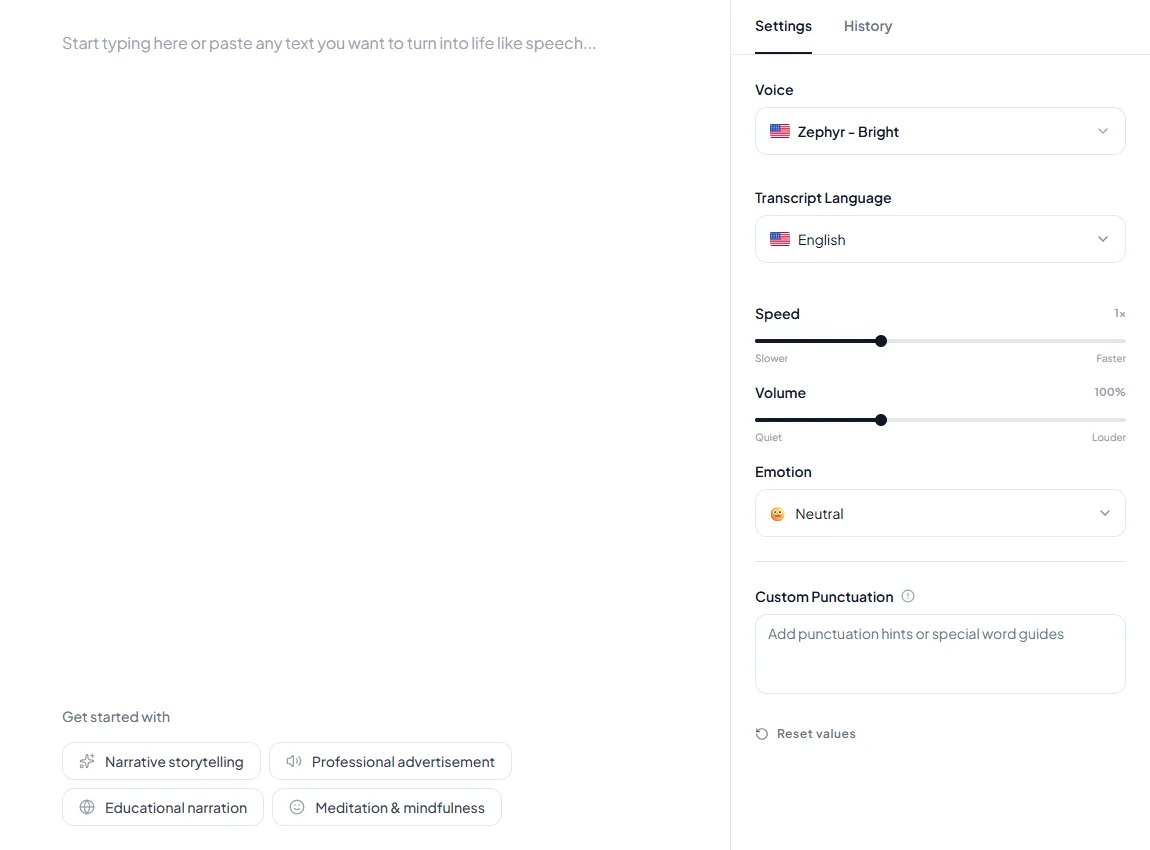
> - **Kveeky gives you speed and volume control** plus an Emotion dropdown with 6 options (Neutral, Happy, Love, Angry, Calm, Sad). It has no pitch control.

**On this page:** [What is prosody](#what-is-prosody) · [Why it matters](#why-prosody-modeling-matters) · [How it works](#how-prosody-modeling-works) · [Controllable models](#models-with-controllable-prosody) · [How to control it](#controlling-prosody-step-by-step) · [Examples](#prosody-examples-by-video-type) · [FAQ](#frequently-asked-questions)

## What is prosody?

Prosody is the rhythm, stress and intonation of speech. Linguists call it "suprasegmental", because it sits on top of individual sounds and spans syllables, words and whole sentences.

Prosody tells the listener how to read the words. It signals a question, marks the important word, shows where one idea ends and carries emotion.

<table>
<thead>
<tr><th>Prosodic cue</th><th>What it is</th><th>Example of what it signals</th></tr>
</thead>
<tbody>
<tr><td>Intonation</td><td>The rise and fall of pitch</td><td>A rising end often marks a yes/no question</td></tr>
<tr><td>Stress</td><td>Extra weight on a syllable or word</td><td>"I <strong>said</strong> Tuesday" corrects a mistake</td></tr>
<tr><td>Rhythm and tempo</td><td>Speed and the pattern of strong and weak beats</td><td>Faster speech can sound excited or urgent</td></tr>
<tr><td>Pauses</td><td>Silence between words or phrases</td><td>A pause before a reveal builds suspense</td></tr>
<tr><td>Loudness</td><td>Energy or volume</td><td>Louder speech sounds more forceful</td></tr>
</tbody>
</table>

In AI voices, these cues map to 3 measurable features: pitch (also called F0, the fundamental frequency), duration of sounds and pauses, and energy.

## Why prosody modeling matters

It's one of the most important parts. A voice can pronounce every word correctly and still sound robotic if the prosody is wrong.

Listeners use prosody to follow meaning. Without it, they can't hear which word matters, where a sentence ends or whether a line is a joke. Flat prosody also tires people out over a long video.

Good prosody does 3 jobs in a voiceover:

- **Clarity.** Stress on the key word and pauses between ideas make the message easy to follow.
- **Engagement.** Pitch movement and changes in pace keep attention, while a monotone voice invites viewers to tune out.
- **Character.** Different pacing and pitch patterns give each narrator or character a distinct personality.

If your voiceover sounds stiff, prosody is usually the cause. Our checklist on how to [make an AI voiceover sound less robotic](https://kveeky.com/blog/how-to-make-your-ai-voiceover-sound-less-robotic-in-5-minutes) gives quick fixes.

## How prosody modeling works

Prosody modeling has moved through 3 generations. Each one learned more from data and needed fewer hand-written rules.

<table>
<thead>
<tr><th>Approach</th><th>How it works</th><th>Strength</th><th>Weakness</th></tr>
</thead>
<tbody>
<tr><td>Rule-based</td><td>Linguists write rules for pitch and timing</td><td>Easy to understand and control</td><td>Sounds mechanical; rules for every language</td></tr>
<tr><td>Statistical (for example HMMs)</td><td>Learns probable pitch and timing patterns from labelled speech</td><td>Handles new sentences better</td><td>Needs labelled data; harder to fine-tune</td></tr>
<tr><td>Neural networks</td><td>Learns prosody directly from large amounts of speech</td><td>Much more natural and expressive</td><td>Harder to control exact details</td></tr>
</tbody>
</table>

Many neural models predict prosody as separate features. The FastSpeech 2 paper (Ren and colleagues, 2020) extracts duration, pitch and energy from recorded speech during training. It then predicts those values for new text when it generates audio.

### What the model looks at in your text

To predict prosody, a model analyzes your script on several levels:

- **Grammar.** Content words such as nouns, verbs and adjectives usually get more stress than words like "the" or "of".
- **Sentence structure.** Clause boundaries suggest where to pause and where pitch should reset.
- **New versus known information.** Words that introduce new information usually get more emphasis than words already mentioned.
- **Punctuation.** Commas, periods and question marks are strong hints for pauses and pitch.

That's why rewriting a sentence often fixes delivery faster than any setting. For the full pipeline from text to audio, see [how text-to-speech AI works](https://kveeky.com/blog/how-does-text-to-speech-work).

## Models with controllable prosody

Most modern AI voice tools offer some prosody control, but the type and depth vary. Look at which of these 4 control types a tool supports.

<table>
<thead>
<tr><th>Control type</th><th>What you can change</th><th>Best for</th></tr>
</thead>
<tbody>
<tr><td>Global settings</td><td>Speed, pitch and tone for the whole read</td><td>Quick fixes across a full script</td></tr>
<tr><td>Emotion settings or styles</td><td>The emotion of a line or section</td><td>Hooks, stories and character lines</td></tr>
<tr><td>SSML markup</td><td>Exact pauses, emphasis, pitch, rate and volume</td><td>Precise, word-level control</td></tr>
<tr><td>Script and punctuation</td><td>Phrasing, pauses and stress through wording</td><td>Every tool, every time</td></tr>
</tbody>
</table>

In [Kveeky](https://kveeky.com/), you can adjust speed and volume, choose an emotion from the Emotion dropdown, and add custom punctuation hints. There is no pitch control, so choose a voice that already sits where you want it. Our guide to [emotion control in AI voiceovers](https://kveeky.com/blog/ai-voice-with-emotion) covers which emotions suit which scripts.

Tools that support SSML follow the W3C standard. Its `<prosody>` element can change pitch, contour, range, rate, duration and volume. Its `<break>` and `<emphasis>` elements handle pauses and stress. Support differs between tools, so check the docs first.

### How Kveeky helps

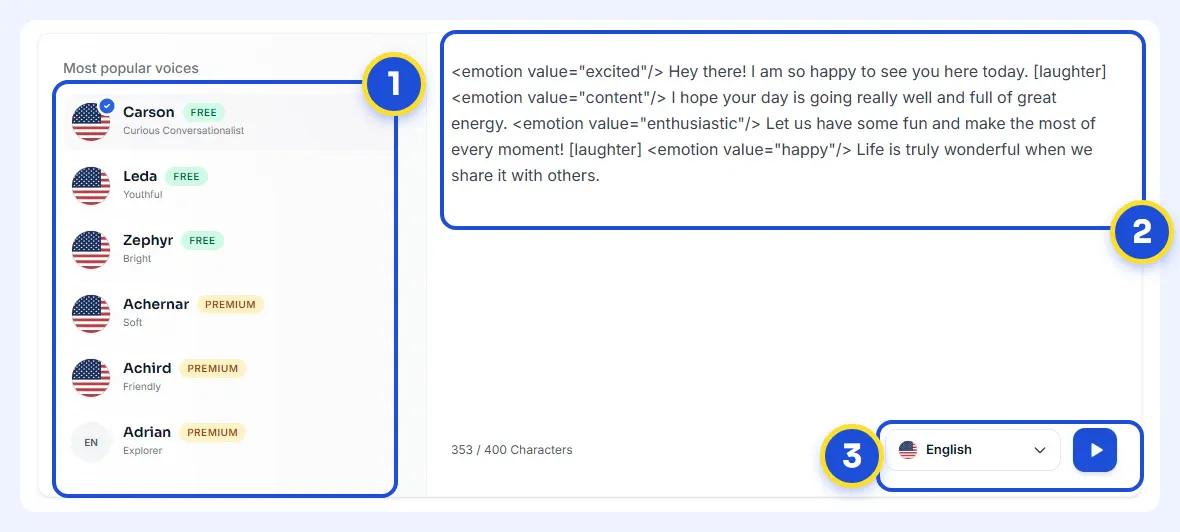
<figure style="margin:28px 0;padding:0"><a href="https://kveeky.com/"><img src="https://cdn.kveeky.com/portals/public-uploads/c033eba2-39d4-4683-a5a9-c8cf2ffc6d01.webp" alt="The Kveeky homepage voice demo with three numbered areas: the voice list, the script box and the language and play controls." width="1180" height="532" loading="lazy" decoding="async" style="display:block;width:100%;height:auto;border-radius:14px;border:1px solid #dbeafe"></a><figcaption style="margin-top:12px"><ol style="margin:0;padding:0"><li style="display:flex;gap:10px;align-items:flex-start;margin:0 0 6px;padding:0;list-style:none"><span style="flex:0 0 24px;height:24px;border-radius:50%;background:#1d4ed8;color:#fff;font:700 13px/24px var(--kv-font-heading);text-align:center">1</span><span style="font:400 15px/1.5 var(--kv-font-body);color:#1f2937"><span style="font-weight:700">Pick a voice.</span> Voices are tagged Free or Premium.</span></li><li style="display:flex;gap:10px;align-items:flex-start;margin:0 0 6px;padding:0;list-style:none"><span style="flex:0 0 24px;height:24px;border-radius:50%;background:#1d4ed8;color:#fff;font:700 13px/24px var(--kv-font-heading);text-align:center">2</span><span style="font:400 15px/1.5 var(--kv-font-body);color:#1f2937"><span style="font-weight:700">Type or paste a short line.</span> Pick an emotion if you want one.</span></li><li style="display:flex;gap:10px;align-items:flex-start;margin:0 0 6px;padding:0;list-style:none"><span style="flex:0 0 24px;height:24px;border-radius:50%;background:#1d4ed8;color:#fff;font:700 13px/24px var(--kv-font-heading);text-align:center">3</span><span style="font:400 15px/1.5 var(--kv-font-body);color:#1f2937"><span style="font-weight:700">Choose the language and press play</span> to hear it.</span></li></ol><p style="margin:6px 0 0;font:400 14px/1.5 var(--kv-font-body);color:#6b7280">Try it yourself in the free voice demo on <a href="https://kveeky.com/" style="font:inherit;color:#1d4ed8">Kveeky</a>, no sign-up needed. For longer scripts and downloads, use the free plan.</p></figcaption></figure>

<figure style="margin:28px 0;padding:0"><img src="/blog/product/app-text-to-speech.webp" alt="The Kveeky text-to-speech editor with a script box and a settings panel showing Voice, Transcript Language, Speed, Volume, Emotion and Custom Punctuation." width="1150" height="850" loading="lazy" decoding="async" style="display:block;width:100%;height:auto;border-radius:14px;border:1px solid #dbeafe"><figcaption style="margin-top:12px;font:400 15px/1.5 var(--kv-font-body);color:#4b5563">The Kveeky text-to-speech editor. Your script goes in the box. In Settings, <strong>Speed</strong> sets the pace of the whole read and <strong>Emotion</strong> lets you choose from 6 options. <strong>Custom Punctuation</strong> takes punctuation hints and word guides. Change one setting, generate, and listen before you touch the next.</figcaption></figure>

## Controlling prosody step by step

Use this order. The early steps fix most problems, so you'll rarely need the later ones.

1. **Write for the ear.** Short sentences, contractions and plain words give the model clear phrasing.
2. **Place punctuation on purpose.** Commas for small breaths, periods for full stops and question marks for rising pitch.
3. **Put the key word where stress falls.** Moving it to the end of a sentence, or into its own short sentence, often works.
4. **Set speed and pitch for the whole read.** Make small changes and listen after each one.
5. **Add emotion where the mood changes.** Tag the hook, the turning point and the call to action.
6. **Use SSML for exact control, if supported.** For example, `Here's the <emphasis level="strong">important</emphasis> part. <break time="500ms"/>`
7. **Listen with the video.** Prosody that sounds fine alone may need more pauses to match the visuals.

<div style="margin:28px 0;padding:18px 20px;border:1px solid #dbeafe;border-radius:12px;background:#ffffff"><div style="font:700 17px/1.3 var(--kv-font-heading);color:#172554;margin-bottom:6px">Prosody check: 5 ticks before you export</div><p style="margin:0 0 10px;font:400 15px/1.5 var(--kv-font-body);color:#4b5563">Run it on your script once. Takes about two minutes.</p><label style="display:flex;align-items:flex-start;gap:12px;min-height:44px;padding:8px 0;font:400 16px/1.5 var(--kv-font-body);color:#1f2937;cursor:pointer"><input type="checkbox" style="width:22px;height:22px;margin-top:2px;flex:none;accent-color:#1d4ed8"><span>Every sentence is short enough to say in one breath.</span></label><label style="display:flex;align-items:flex-start;gap:12px;min-height:44px;padding:8px 0;font:400 16px/1.5 var(--kv-font-body);color:#1f2937;cursor:pointer"><input type="checkbox" style="width:22px;height:22px;margin-top:2px;flex:none;accent-color:#1d4ed8"><span>The key word of each sentence sits where the stress should fall.</span></label><label style="display:flex;align-items:flex-start;gap:12px;min-height:44px;padding:8px 0;font:400 16px/1.5 var(--kv-font-body);color:#1f2937;cursor:pointer"><input type="checkbox" style="width:22px;height:22px;margin-top:2px;flex:none;accent-color:#1d4ed8"><span>Commas, periods and question marks match the pauses I want to hear.</span></label><label style="display:flex;align-items:flex-start;gap:12px;min-height:44px;padding:8px 0;font:400 16px/1.5 var(--kv-font-body);color:#1f2937;cursor:pointer"><input type="checkbox" style="width:22px;height:22px;margin-top:2px;flex:none;accent-color:#1d4ed8"><span>Emotion is tagged only where the mood changes: the hook, the turning point and the call to action.</span></label><label style="display:flex;align-items:flex-start;gap:12px;min-height:44px;padding:8px 0;font:400 16px/1.5 var(--kv-font-body);color:#1f2937;cursor:pointer"><input type="checkbox" style="width:22px;height:22px;margin-top:2px;flex:none;accent-color:#1d4ed8"><span>I played the voice against the video and added pauses where the visuals need them.</span></label></div>

For detailed timing techniques, see our guide to [pacing, pauses and emphasis tricks](https://kveeky.com/blog/adding-personality-to-ai-voices-pacing-pauses-emphasis-tricks).

## Prosody examples by video type

Different videos need different prosody. Use this as a starting point.

<table>
<thead>
<tr><th>Video type</th><th>Pitch</th><th>Pace and pauses</th><th>Stress</th></tr>
</thead>
<tbody>
<tr><td>E-learning</td><td>Friendly, varied</td><td>Moderate; pause after key terms</td><td>On new terms, such as "myocardium"</td></tr>
<tr><td>Marketing video</td><td>Higher energy in the hook</td><td>Faster hook, clear pause before the offer</td><td>On the benefit and the call to action</td></tr>
<tr><td>Financial explainer</td><td>Steady, lower</td><td>Measured; slower on numbers</td><td>On figures and the main conclusion</td></tr>
<tr><td>Story or animation</td><td>Wide range per character</td><td>Varied; long pauses for tension</td><td>On emotional words</td></tr>
</tbody>
</table>

### Example: a 15-second marketing voiceover in Kveeky

Paste a short script, pick a voice and choose an emotion for each section (Happy for the hook, Calm for the close):

```
Tired of editing the same video 5 times?   (Happy)
Plan it once. Publish everywhere.            (Calm)
Try it free today.                           (Calm)
```

Set the speed slightly faster for the hook, listen once and download the audio. Then line up your cuts with the voice. For more on ad reads, see our page on [AI voiceover for advertisements](https://kveeky.com/voiceover/advertisements/). To pick a voice that fits your audience, read our guide to [matching AI voice tone to your niche](https://kveeky.com/blog/ai-voice-tone-niche-strategy).

<details style="margin:20px 0;border:1px solid #dbeafe;border-radius:12px;background:#ffffff"><summary style="min-height:44px;display:flex;align-items:center;padding:6px 16px;font:600 16px/1.4 var(--kv-font-body);color:#172554;cursor:pointer">Show me: one line, three ways to stress it</summary><div style="padding:0 16px 16px;font:400 16px/1.6 var(--kv-font-body);color:#1f2937"><p style="margin:0 0 10px">Take the line "I said Tuesday" from the table above. The words stay the same, so the stress decides the meaning. Mark the stressed word before you generate the voice.</p><ol style="margin:0;padding-left:22px"><li style="margin:0 0 8px"><strong>"I said Tuesday."</strong> Stress on <em>said</em>. It corrects a mistake: I told you already.</li><li style="margin:0 0 8px"><strong>"I said Tuesday."</strong> Stress on <em>I</em>. It shows who said it, not someone else.</li><li style="margin:0 0 8px"><strong>"I said, Tuesday."</strong> The comma adds a small pause that sets up the day.</li></ol><p style="margin:12px 0 0">If the voice stresses the wrong word, rewrite the sentence so the key word comes last, or give it a short sentence of its own, then regenerate and listen again.</p></div></details>

## Frequently asked questions

### What is prosody in speech?

Prosody is the rhythm, stress, intonation and pausing of speech. It shows which words matter, whether a line is a question and how the speaker feels.

### What's the difference between prosody and intonation?

Intonation is one part of prosody: the rise and fall of pitch. Prosody also includes stress, rhythm, tempo, pauses and loudness.

### What are prosodic cues?

Prosodic cues are the signals in pitch, timing, stress and loudness that listeners use to understand meaning. A rising pitch at the end of a sentence is a common example.

### How do you describe tone of voice?

Use 2 or 3 words for pitch, pace and feeling, such as "warm, slow and calm" or "bright, fast and playful". These words also make good notes when you choose an AI voice.

### Can voiceover software adjust pacing automatically to video content?

Most text-to-speech tools set pacing from the text, not from the video. Write the script to the video's timing, adjust speed by section and then edit the cuts to the voice.

### Does SSML work in every text-to-speech tool?

No. SSML is a W3C standard, but each tool supports a different set of tags. Check your tool's docs, and use punctuation and settings where tags aren't supported.

## How we checked this guide

This guide is written by Hitesh Kumawat for the Kveeky team. **Disclosure: Kveeky makes an AI voice generator.**

- The FastSpeech 2 description comes from Ren and colleagues, "[FastSpeech 2: Fast and High-Quality End-to-End Text to Speech](https://arxiv.org/abs/2006.04558)", arXiv, 2020, retrieved October 6, 2026.
- SSML element names and attributes come from the [W3C Speech Synthesis Markup Language (SSML) Version 1.1](https://www.w3.org/TR/speech-synthesis11/) specification, retrieved October 6, 2026.
- Kveeky features come from kveeky.com, retrieved October 6, 2026. No Kveeky usage data is used in this guide.

Your next step: take one line from your current script, say it out loud the way you want it heard, and mark the stressed word and the pauses. Then rewrite and regenerate that line until the AI voice matches your reading.

<script type="application/ld+json">
{"@context":"https://schema.org","@type":"FAQPage","mainEntity":[
{"@type":"Question","name":"What is prosody in speech?","acceptedAnswer":{"@type":"Answer","text":"Prosody is the rhythm, stress, intonation and pausing of speech. It shows which words matter, whether a line is a question and how the speaker feels."}},
{"@type":"Question","name":"What's the difference between prosody and intonation?","acceptedAnswer":{"@type":"Answer","text":"Intonation is one part of prosody: the rise and fall of pitch. Prosody also includes stress, rhythm, tempo, pauses and loudness."}},
{"@type":"Question","name":"What are prosodic cues?","acceptedAnswer":{"@type":"Answer","text":"Prosodic cues are the signals in pitch, timing, stress and loudness that listeners use to understand meaning. A rising pitch at the end of a sentence is a common example."}},
{"@type":"Question","name":"How do you describe tone of voice?","acceptedAnswer":{"@type":"Answer","text":"Use 2 or 3 words for pitch, pace and feeling, such as \"warm, slow and calm\" or \"bright, fast and playful\". These words also make good notes when you choose an AI voice."}},
{"@type":"Question","name":"Can voiceover software adjust pacing automatically to video content?","acceptedAnswer":{"@type":"Answer","text":"Most text-to-speech tools set pacing from the text, not from the video. Write the script to the video's timing, adjust speed by section and then edit the cuts to the voice."}},
{"@type":"Question","name":"Does SSML work in every text-to-speech tool?","acceptedAnswer":{"@type":"Answer","text":"No. SSML is a W3C standard, but each tool supports a different set of tags. Check your tool's docs, and use punctuation and settings where tags aren't supported."}}
]}
</script>