On this page
Voice style transfer is an AI technique that changes how a voice speaks without changing what it says. It can move the emotion, energy, pace or accent of one recording onto another voice. It can also make one speaker sound like another. Video producers use it to keep a consistent brand voice and to create character voices.
Last updated: October 7, 2026. Research papers cited below were checked on arXiv on that date.
This guide is for video producers, editors and creators who keep hearing the term and want to know what it means in practice. It explains how it works, the research behind it, what you can do with it today, and where it still falls short.
Key Takeaways
- Style is the "how", content is the "what". Style transfer keeps the words and changes the delivery, such as calm to excited, or one speaker to another.
- The core trick is separating style from content. Models learn to split a recording into what was said and how it was said, then swap the "how".
- Global Style Tokens (2018) and AutoVC (2019) are key research milestones. AutoVC was the first to perform zero-shot voice conversion, according to its authors.
- You can get most of the benefit in a TTS tool today with emotion, speed and pace controls, and voice cloning.
- Get consent. Copying a real person's voice or style needs their permission.
Voice style transfer changes how a voice speaks (emotion, pace, energy, accent or even the speaker) without changing the words. Research models do it by separating content from style. In practice, video producers get most of the benefit from a text-to-speech tool: pick a voice, set the speed and emotion, and compare two or three takes of the same line.
On this page: What it is · Compared · How it works · AutoVC · Uses · In practice · Limits · FAQ
What is voice style transfer?
Voice style transfer, also called speech style transfer, changes the style of a voice while keeping the message. "Style" can mean several things:
- Emotion: happy, sad, angry, calm.
- Energy and pace: a fast sports commentator versus a slow bedtime story.
- Speaking style: news read, casual vlog, whisper, ad read.
- Accent: how vowels and rhythm sound in a given region.
- Speaker identity: whose voice it sounds like at all.
Standard text-to-speech (TTS) focuses on reading text correctly. Style transfer focuses on delivery. In real tools, the 2 are now often combined: you type text, and the system reads it in a chosen style.
Style transfer vs cloning vs conversion
These terms overlap, and people use them loosely. Here's how they usually differ.
| Term | Input | What changes | Example |
|---|---|---|---|
| Voice style transfer | Text or speech, plus a style reference | Delivery: emotion, pace, energy, accent | Read the same script calm, then excited |
| Voice conversion | Speech from speaker A | Speaker identity, so A sounds like B | Your recording re-voiced as a character |
| Voice cloning | A sample of a voice, then text | Creates a reusable copy of that voice | Type any script in your own voice |
| Text-to-speech | Text | Turns text into speech in a stock voice | A narrator voice for a tutorial |
Researchers often treat voice conversion as one kind of style transfer, where the "style" is the speaker. That's why the AutoVC paper, covered below, uses both terms. For cloning a voice from a few seconds of audio, see our guide to zero-shot voice cloning.
Matches the comparison table above.
How style transfer AI works
Almost every method follows the same idea: split a recording into content and style, then recombine the content with a new style. Here's the process in 4 steps.
- Analyze the audio. The model turns speech into features, often a spectrogram that shows pitch and energy over time.
- Separate content from style. An encoder learns one representation for the words and sounds, and another for the delivery or the speaker.
- Swap in a new style. The style part is replaced with one taken from a reference clip or a chosen setting, such as "excited".
- Rebuild the speech. A decoder and a vocoder turn the new mix back into audio.
The hard part is step 2. If the content still carries some of the old style, the result sounds like a blend. If too much content is removed, words get blurry.
Style tokens: learning style without labels
A 2018 paper by Yuxuan Wang and co-authors introduced Global Style Tokens. The model learned a small set of style "building blocks" with no explicit labels. Those tokens could then control pace and speaking style separately from the text, and copy the style of one clip across a longer passage (arXiv 1803.09017, retrieved 2026-10-06).
Prosody transfer: copying rhythm and emphasis
Prosody is the rhythm, stress and pitch movement of speech. Prosody transfer copies those patterns from one recording to another. It's the part of style you notice most in a voiceover. Our guide to prosody modeling in AI voiceovers explains it in detail.
For the model types behind all of this, including encoders, decoders, autoencoders and GANs, see our explainer on neural network architectures for AI voice generation.
AutoVC zero-shot transfer
AutoVC is a well-known research model for voice conversion. Its paper is titled "AUTOVC: Zero-Shot Voice Style Transfer with Only Autoencoder Loss". It was presented at ICML 2019 by Kaizhi Qian and co-authors (arXiv 1905.05879, retrieved 2026-10-06).
Here's the idea in plain English:
- An autoencoder with a tight bottleneck. An autoencoder squeezes speech into a small code, then rebuilds it. AutoVC makes that code so small that speaker details can't fit through, while the content can.
- Speaker identity comes from outside. When rebuilding, the model is told which speaker to sound like. Swap that input, and the same content comes out in a different voice.
- Simple training. The authors showed that this works using only a reconstruction loss, without the harder GAN training.
- Zero-shot. The authors say AutoVC was the first to perform zero-shot voice conversion, meaning conversion to or from speakers it never saw in training.
AutoVC is a research model, not a creator tool. If you'd like to experiment with open models yourself, our guide to the Coqui TTS open-source toolkit is a practical starting point.
Uses for video producers
Style transfer matters to video producers because delivery changes how viewers feel about the same words.
- Consistent brand voice across videos. Keep one voice, but adapt the style: upbeat for ads, calm for tutorials, warm for onboarding. A written brand voice guide for AI voiceovers helps you define those styles.
- Character voices. Give animated characters distinct deliveries, such as a slow, deep owl and a fast, bright fox, without hiring a separate actor for each draft.
- E-learning. Use a lively style for introductions and a slower, steadier style for complex steps.
- Localization. Keep a similar tone when a video is voiced in another language, so the brand feels the same.
- Fixing a take. Re-voice a line in a different emotion without booking another session.
For ready-made character voices, browse our library of character and anime AI voices.
Style transfer in a TTS tool
You don't need to train a research model. Most of what video producers want from style transfer is possible in a modern TTS tool, with a few controls.
- Pick or clone a base voice. Choose a stock voice, or create a voice clone with the speaker's consent.
- Write the script for the style. Short, punchy lines for an energetic read. Longer, calmer lines for a documentary read.
- Set the delivery. Adjust speed and tone, and add emotion where needed.
- Generate 2 or 3 versions. Compare a neutral, a warm and an energetic version of the same line.
- Pick and export. Download the best take and drop it into your editor.
In Kveeky, for example, you can choose from 700+ AI voices in 40+ languages and adjust speed and volume. The Emotion setting (Neutral, Happy, Love, Angry, Calm or Sad) changes how a line is read. See the pricing page for what voice cloning includes.
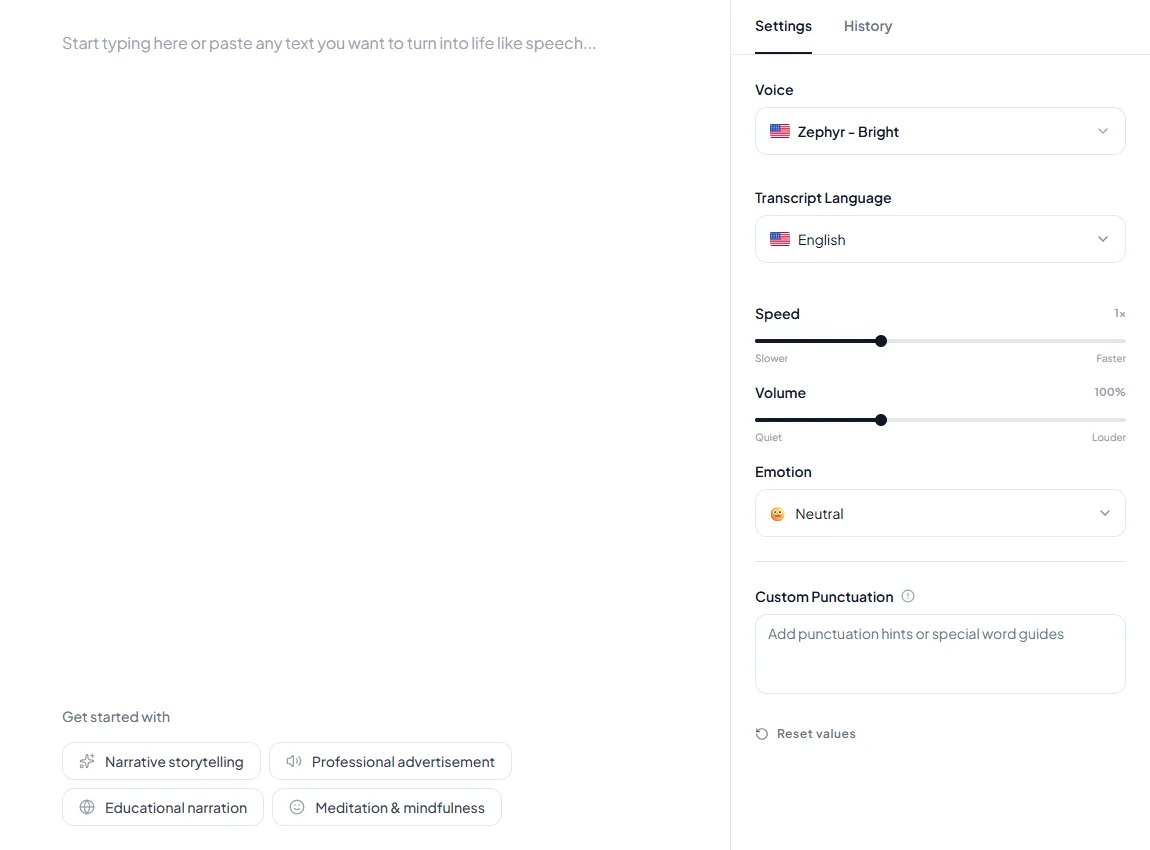
This isn't the same as copying the exact style of one recording onto another voice. For most videos, though, controlling emotion and pace gets you the result you need.
Shows the starting settings from the recipe table below, in Kveeky's terms (Speed and Emotion). Adjust by ear.
Speed: Slightly faster than default
Emotion: Happy
Test line: Meet the faster way to send invoices.
Style recipes for 6 common video types
Use these as starting points, then adjust by ear. Speeds are relative to the voice's default (1.0×). Keep the same base voice across all of them if you want one recognizable brand voice with different moods.
| Video type | Target style | Script pattern | Speed | Pitch | Emotion | Test line |
|---|---|---|---|---|---|---|
| Product ad (15–30 s) | Bright, confident | Short sentences, verb first | 1.05–1.1× | Slightly up | Excited | "Meet the faster way to send invoices." |
| Tutorial or how-to | Calm, clear | One action per sentence | 0.9–0.95× | Neutral | None or calm | "Click Settings, then choose Export." |
| Documentary narration | Measured, serious | Longer sentences, pauses at commas | 0.85–0.9× | Slightly down | Calm | "By 1900, the river had changed course twice." |
| Onboarding or welcome | Warm, friendly | Second person, contractions | 1.0× | Neutral | Happy | "You're all set. Let's take a quick tour." |
| Short-form social clip | High energy | Hook in the first 5 words | 1.1–1.15× | Up | Excited | "Stop scrolling: this saves you an hour." |
| Animated character | Exaggerated, distinct | Character quirks in the wording | 0.8× (slow) or 1.2× (fast) | Far down or far up | Matches the scene | "Well, well… what do we have here?" |
Kveeky has no pitch control and its emotions are Neutral, Happy, Love, Angry, Calm and Sad, so use Happy where the table says Excited and ignore the Pitch column there. The Pitch column applies to tools that have it.
A quick check for any recipe: if a listener can describe the mood in one word ("calm", "upbeat") after one play, the style landed. If they say "robotic" or "too much", move speed (and pitch, in tools that have it) back toward 1.0× and neutral. For more on delivery, see our guide to prosody modeling for AI voiceovers.
Limits and ethics
Style transfer has improved fast, but it isn't perfect.
- Strength vs quality. Push a style too hard and speech can sound exaggerated or muffled. A light touch often sounds more natural.
- Data needs. Rare styles and accents need good example recordings. With little data, the model falls back to a default delivery.
- Language differences. Emphasis works differently across languages. In tonal languages such as Mandarin Chinese, pitch changes can change a word's meaning.
- Real-time use is harder. Live conversion must run fast enough to avoid a noticeable delay.
The ethical risks are real too. Converting your voice into a real person's voice, or copying their signature style, can mislead viewers. Get written consent, label synthetic voices where viewers could be misled, and follow each platform's rules. Our guide to the ethics of AI voice cloning in video production covers this in depth.
Not sure whether you need style transfer, a voice changer or text to speech? Compare them in voice changer vs text to speech vs voice cloning.
Frequently asked questions
What is voice style transfer in AI?
It's an AI technique that changes how a voice speaks, such as its emotion, pace, accent or speaker identity, while keeping the same words. It works by separating content from style, then combining the content with a new style.
Is voice style transfer the same as voice cloning?
No. Voice cloning creates a reusable copy of a specific voice from a sample. Style transfer changes the delivery of speech, such as making it calmer or more excited. Many tools combine both, so you can clone a voice and then control its style.
What is AutoVC?
AutoVC is a 2019 research model for voice conversion, presented at ICML. It uses an autoencoder with a small bottleneck to separate content from speaker identity. Its authors say it was the first to perform zero-shot voice conversion.
Is there an app for voice style transfer?
Most AI voice generators offer style controls rather than full style transfer. You can pick or clone a voice, then change emotion, speed and pitch. Research models like AutoVC are published as papers and need technical skill to run.
Can I use style transfer to copy a celebrity's voice?
Not without permission. Copying a real person's voice or recognizable style without consent can mislead audiences and may break platform rules and likeness laws. Use your own voice, a stock voice, or a voice you have written permission to use.
How we checked this guide
This guide is written by Govind Kumar for the Kveeky team. Disclosure: Kveeky makes an AI voice generator. No Kveeky usage data is used in this guide.
- Global Style Tokens: Wang et al., "Style Tokens: Unsupervised Style Modeling, Control and Transfer in End-to-End Speech Synthesis", arXiv 1803.09017, retrieved 2026-10-06.
- AutoVC: Qian et al., "AUTOVC: Zero-Shot Voice Style Transfer with Only Autoencoder Loss", ICML 2019, arXiv 1905.05879, retrieved 2026-10-06.
- Kveeky features and plan details: kveeky.com/pricing, retrieved 2026-10-06.
Your next step: take one 20-second line from your next video and generate it in 3 styles: neutral, warm and energetic. Play all 3 to a colleague and keep the one that fits the message. If you want the technical background first, start with our hub guide on how text-to-speech AI works.
Turn your script into a voiceover
Paste your text, pick a voice and download the audio. Free to start, no credit card.