How Does Text to Speech Work? Understanding Text-to-Speech AI
TL;DR
- ✓ Text-to-speech AI converts written text into natural human speech using neural synthesis.
- ✓ The process involves normalization, acoustic modeling, and conversion via a neural vocoder.
- ✓ Transformer-based models predict sound frequencies to create authentic vocal rhythm and tone.
- ✓ Edge AI reduces latency by running speech models locally on device hardware.
How does text to speech work? A text-to-speech (TTS) engine turns your script into audio in 3 stages. A front end reads the text, an acoustic model plans the delivery, and a vocoder turns that plan into a waveform you can play.
Last updated: October 7, 2026. Research claims were checked against the original papers on arXiv and the W3C SSML specification, and we added quick answers to common text to speech questions.
This guide is for creators, teachers and small teams who use AI voices. It shows what happens between "paste script" and "download MP3." You don't need any math. Each section answers one question and links to a deeper guide if you want more.
Key Takeaways
- 3 stages: every modern TTS engine has a text front end, an acoustic model and a vocoder. Problems in your audio usually trace back to one of them.
- Yes, modern text to speech is AI. Today's voices come from neural networks trained on recorded speech. Older systems used hand-written rules or stitched recordings together.
- It is generative AI too. A neural TTS model creates new audio that was never recorded. It does not play back stored clips.
- Natural sound comes from prosody, the rhythm, stress and pitch of speech. In the Tacotron 2 paper, listeners scored it 4.53 out of 5 versus 4.58 for professionally recorded speech (arXiv, 2017, retrieved 2026-10-06).
- You control the result with punctuation, respelling and delivery settings. In Kveeky that means emotion tags plus tone, pitch and speed controls.
On this page: The 3-stage pipeline · Is TTS AI? · How voices are made · Why it sounds natural · Controlling the read · Speech to speech · Cloud or local · Quick answers · FAQ
How does text to speech work? The 3-stage pipeline
A text to speech engine is the software that does the whole conversion. Inside it, 3 parts hand work to each other like a relay team.
Stage 1: the front end reads and cleans your text
Computers don't read the way people do. The front end expands "Dr." to "Doctor," "3 PM" to "three P M" and "$9" to "nine dollars." This step is called text normalization.
It then converts words into phonemes, the small sound units of a language. The word "read" needs context here, because it sounds different in "I read it yesterday" and "I'll read it now."
Stage 2: the acoustic model plans the delivery
The acoustic model is the "brain" of the system. It takes the phonemes and predicts how long each sound lasts, how high the pitch goes and which words get stress.
Most models write this plan as a mel spectrogram. Think of it as sheet music for speech: a picture of which frequencies are loud at each moment. For the model families that do this, such as Tacotron, FastSpeech and Transformer TTS, see our guide to the neural network architectures behind AI voices.
Stage 3: the vocoder makes the sound
A spectrogram is not audio yet. The vocoder fills in the fine detail, thousands of samples per second, and outputs a waveform your speakers can play.
The vocoder has a big effect on how real a voice sounds. Older vocoders often left a buzzy, metallic edge. Our deep dive on how neural vocoders turn spectrograms into sound explains why newer ones sound cleaner.
Is text to speech AI? From rules to neural networks
Yes, modern text to speech is AI. Today's AI voice tools use neural networks that learn speech from recordings. Older TTS used hand-written rules or recorded fragments, which is not AI in the modern sense.
Here is how the approaches compare.
| Approach | How it makes sound | What it sounds like | Is it AI? |
|---|---|---|---|
| Formant (rule-based) | Hand-written rules shape a synthetic sound source | Clear but obviously robotic | No |
| Concatenative | Stitches together short clips cut from one person's recordings | Natural words, audible joins between them | Not in the modern sense |
| Statistical parametric | A statistical model, often a hidden Markov model, predicts speech features | Smooth but muffled and flat | Early machine learning |
| Neural TTS | Neural networks generate the spectrogram and the waveform | Natural rhythm and tone, few artifacts | Yes |
The turning point came in 2016. In the WaveNet paper, listeners rated a neural model as clearly more natural than the best older systems. That held for both English and Mandarin (van den Oord et al., arXiv, retrieved 2026-10-06).
Is text to speech generative AI?
Neural text to speech is a form of generative AI. The model doesn't search a library of recorded clips. It generates a new waveform for every script, based on patterns it learned from training audio.
Speech to text runs the other way. It also uses neural networks, but its job is recognizing words in audio, not creating new audio.
How are AI text to speech voices made?
TTS voices are made by training a neural model on recordings of a real person, matched to the text they read. Most AI voices start with many hours of scripted reading. The model learns how that speaker's voice maps from text to sound. After training, it can say sentences the speaker never recorded.
So does text to speech use real voices? Indirectly, yes. The voice is learned from a real speaker, but each sentence you generate is new audio, not a playback of a stored recording.
Multi-speaker models go further. They store each voice as a speaker embedding, a short list of numbers that acts like a fingerprint for timbre and accent. Switching voices then means switching fingerprints, not training a new model.
Voice cloning uses the same idea with far less audio. The VALL-E research model produced speech in an unseen speaker's voice from a 3-second recording (Wang et al., arXiv, 2023, retrieved 2026-10-06). Our explainer on zero-shot voice cloning covers how that works and where it falls short.
What makes AI speech sound natural instead of robotic?
The difference between robotic and natural speech is mostly prosody: rhythm, stress, pitch movement and pauses. Getting each word right isn't enough. A voice that stresses every word equally sounds like a machine, even with perfect pronunciation.
Neural models learn prosody from context. They see a whole sentence and predict that a question rises at the end, a list has small pauses, and a key word gets extra stress. That's the main reason people now ask what makes synthetic speech sound "lifelike."
Researchers measure this with listening tests. The most common is the mean opinion score (MOS), where people rate clips from 1 to 5. Tacotron 2 scored 4.53, close to the 4.58 that professionally recorded speech received (Shen et al., arXiv, retrieved 2026-10-06).
A score like that comes from a lab test on one voice, not from every product. If you want to know how clarity is tested beyond MOS, read our guide on how the intelligibility of synthetic speech is measured.
Neural voices still have weak spots. They can misread rare names, stress the wrong word in long sentences, or keep the same energy through a whole script. Long-form drama with big emotional shifts is still a job where a human voice actor does better.
How do you control the way a TTS voice reads your script?
You control a TTS voice mostly through your text. The front end and acoustic model react to every comma, spelling and line break. Small edits fix most problems, including technical jargon in training videos.
- Use punctuation for pauses. A comma gives a short pause and a full stop a longer one. Break long sentences in two.
- Respell hard words. If a product name or medical term comes out wrong, write it the way it sounds, such as "shi-VAWN" for the name Siobhan.
- Write numbers the way you want them read. "2026" can be read as a year or a quantity. Spell it out if the voice guesses wrong.
- Set the delivery. Pick speed, pitch and emotion to match the scene, then listen once before you export.
Some engines also accept SSML, the Speech Synthesis Markup Language, a W3C standard. Its tags set pauses (<break>), pitch and rate (<prosody>) and stress (<emphasis>). Others control how numbers are read (<say-as>) and exact pronunciation (<phoneme>) (W3C SSML 1.1, retrieved 2026-10-06).
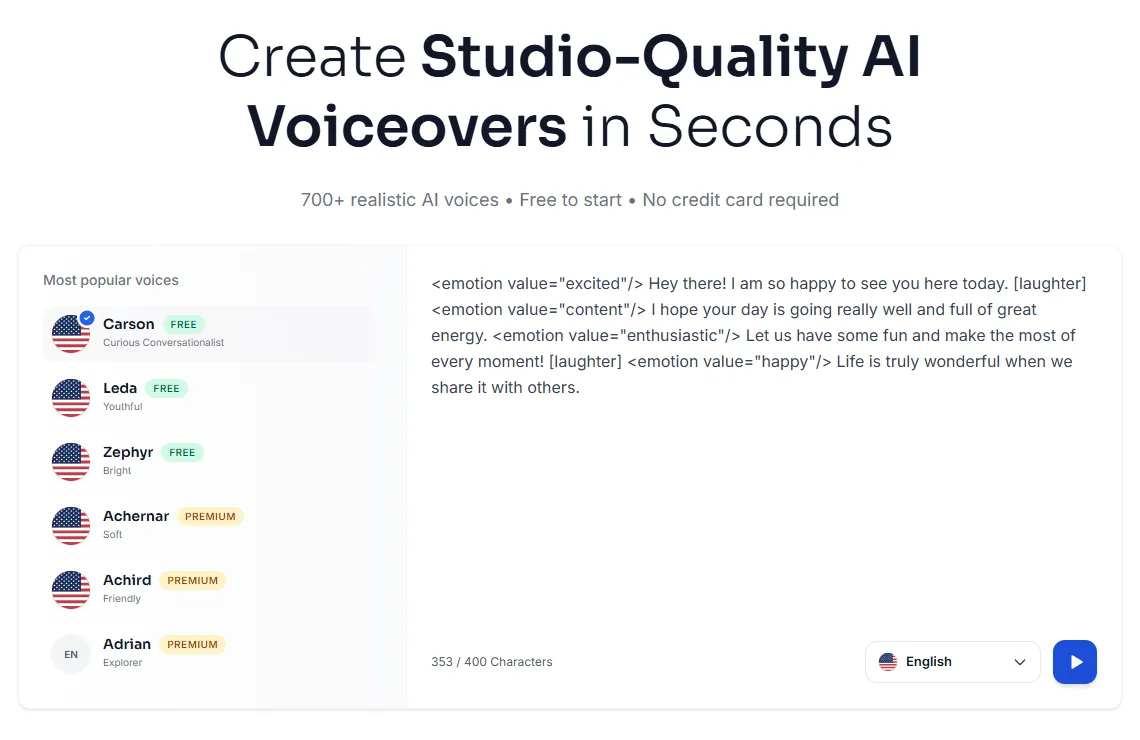
In Kveeky, you paste your script, pick from 700+ voices and adjust tone, pitch and speed. Emotion tags such as <emotion value="excited"/> and [laughter] change how a line is read. You then download MP3 or WAV.
Text to speech vs speech to speech: what's the difference?
Text to speech starts from written words. Speech to speech starts from a recorded performance and changes the voice while keeping its timing and emotion.
Speech to speech AI works like this: a model separates what was said and how it was said from who said it. It keeps the words, pacing and feeling, then rebuilds the audio with a different voice.
It's useful when you want an exact human delivery in another voice. Our voice style transfer guide for video producers covers it in detail.
Where does text to speech run? Cloud or local
Most AI voice tools run in the cloud. You send text, a server with a GPU runs the model, and you get an audio file back. This gives you large voice libraries without any setup.
Local text to speech runs the model on your own computer. It keeps text private and works offline, but you handle installation, hardware and updates yourself. If that appeals to you, start with our overview of open-source TTS toolkits.
Text to speech basics: quick answers to common questions
These short answers cover the questions people ask most about text to speech. Each one links back to the deeper section above where it helps.
What is text-to-speech technology?
Text-to-speech technology is software that reads written text aloud in a synthetic voice. AI voice technology is the modern form of it: neural networks trained on recorded speech that generate new audio for any script. You meet it in screen readers, navigation apps, phone menus and video voiceovers.
Is it called text to speech, text to voice or text to audio?
They mean the same thing.
"Text to speech," shortened to TTS, is the standard technical term. "Text to voice," "text to audio" and "AI voice generator" are everyday names for the same tool. The older academic name is speech synthesis.
What is the difference between text to speech and speech to text?
They run in opposite directions. Text to speech turns written words into audio, while speech to text, also called speech recognition or dictation, turns spoken audio into written words. To go from speech to text and back, transcribe the recording first, edit the transcript, then paste the clean text into a voice tool.
What is the difference between an AI voice and a traditional voiceover?
A traditional voiceover is a human actor recorded in a session, while an AI voice is generated from your script in minutes. AI wins on speed, cost and easy updates, since you can fix one line without booking a studio. A human actor still wins when the performance carries the piece, such as drama, comedy or a high-stakes brand film.
How accurate is AI text to speech?
For everyday words in well-supported languages, modern neural voices are usually accurate and easy to follow. Errors cluster around names, acronyms, numbers, rare words and languages with little training data. Free voices are often older or standard models, so test the exact voice with your hardest sentence before you rely on it.
What are the common challenges in text-to-audio technology?
The main challenges are pronunciation of unusual words, flat delivery over long scripts, uneven quality across languages, and keeping emotion consistent. There are also misuse concerns, since the same technology can imitate real people. Most delivery problems trace back to one of the 3 pipeline stages described at the top of this guide.
What are the advantages and disadvantages of text to speech?
The advantages are speed, low cost, consistent delivery, easy edits and access for people who can't read the screen. The disadvantages are weaker emotional range than a skilled actor, occasional mispronunciations, and a free-tier voice that may sound less natural. Some uses also need a disclosure that the voice is AI.
What are the applications of text to speech?
Text to speech is used for accessibility tools such as screen readers, e-learning and training narration, YouTube and social video voiceovers, phone menus, audiobooks and product demos. Small teams use it most where a script changes often, because regenerating a line takes seconds. See how teams apply it to training and onboarding narration.
What are the latest advancements and the future of text to speech?
Recent research has focused on voice cloning from very short samples, more control over emotion and style, and single models that speak many languages. The likely next steps are better long-form delivery, more natural back-and-forth conversation, and wider use of labels or watermarks that mark audio as AI. Our guide to neural network voice synthesis tracks new models with dated sources.
More guides on how text to speech works
Every guide in this topic, in one place:
- Mastering Voice Style Transfer: A Guide for Video Producers
- Neural Network Voice Synthesis: How AI Voice Architectures Work
- Neural Vocoder Architectures
- Open-Source Toolkit for Text-to-Speech Synthesis
- Understanding Synthetic Speech Intelligibility Metrics for Enhanced AI Voiceovers
- Unlocking Clarity: A Video Producer's Guide to Voice Source Separation in AI Voiceover
- Mastering Voice User Interface (VUI) Design for AI Voiceovers
- Zero-Shot Voice Cloning: The Future of AI Voiceovers for Video Producers
Frequently asked questions
What is the difference between text to speech and speech to text?
They work in opposite directions. Text to speech turns written words into spoken audio, while speech to text, also called speech recognition, turns spoken audio into written words.
Is text to speech AI?
Modern text to speech is AI. Today's voices are produced by neural networks trained on recorded speech. Older rule-based and concatenative systems followed fixed rules or stitched recordings together instead of learning from data.
Is text to speech generative AI?
Neural text to speech is generative AI. The model creates a new audio waveform for each script instead of playing back stored clips. It works on the same principle as AI that generates images or text from learned patterns.
Does text to speech use real voices?
AI voices are usually trained on recordings of real people, so the sound comes from a real speaker. The sentences you generate are new audio, though. The person never recorded those exact words.
How does speech to speech AI work?
Speech to speech AI takes a recorded performance, keeps its words, timing and emotion, and replaces the voice with a different one. It's used for dubbing and character voices when you want a human delivery in another voice.
Can text to speech run offline?
Yes, if you use a local model. Open-source TTS engines can run on your own computer without an internet connection. Most commercial AI voice tools generate audio on their own servers and give you a file to download.
Why does my AI voice mispronounce some words?
The text front end guessed the wrong sounds, usually for names, brands, acronyms or jargon. Respell the word the way it sounds, add punctuation for pauses, or write numbers out in words, then generate the line again.
How we checked this guide
This guide is written by Govind Kumar for the Kveeky team. Disclosure: Kveeky makes an AI voice generator. We explain how TTS works in general and don't describe the internal models of any specific product, including ours.
- Research claims come from the original papers on arXiv, retrieved October 6, 2026: WaveNet (2016), Tacotron 2 (2017) and VALL-E (2023).
- SSML details come from the W3C Speech Synthesis Markup Language 1.1 Recommendation, retrieved October 6, 2026.
- Kveeky features and the 700+ voice count come from kveeky.com/pricing, retrieved October 6, 2026.
- No Kveeky usage data is used in this guide.
Want to hear the pipeline in action? Paste a short training script with one tricky term, respell it once, and compare the two reads. Our page on AI voiceovers for training videos shows how teams use this for course and onboarding narration.