# How Does Text to Speech Work? Understanding Text-to-Speech AI

Published: June 7, 2026 · Author: Govind Kumar

How does text to speech work? A text-to-speech (TTS) engine turns your script into audio in 3 stages. A front end reads the text, an acoustic model plans the delivery, and a vocoder turns that plan into a waveform you can play.

*Last updated: October 7, 2026. Research claims were checked against the original papers on arXiv and the W3C SSML specification, and we added quick answers to common text to speech questions.*

This guide is for creators, teachers and small teams who use AI voices. It shows what happens between "paste script" and "download MP3." You don't need any math. Each section answers one question and links to a deeper guide if you want more.

> **Key Takeaways**
>
> - **3 stages:** every modern TTS engine has a text front end, an acoustic model and a vocoder. Problems in your audio usually trace back to one of them.
> - **Yes, modern text to speech is AI.** Today's voices come from neural networks trained on recorded speech. Older systems used hand-written rules or stitched recordings together.
> - **It is generative AI too.** A neural TTS model creates new audio that was never recorded. It does not play back stored clips.
> - **Natural sound comes from prosody,** the rhythm, stress and pitch of speech. In the Tacotron 2 paper, listeners scored it 4.53 out of 5 versus 4.58 for professionally recorded speech ([arXiv, 2017](https://arxiv.org/abs/1712.05884), retrieved 2026-10-06).
> - **You control the result** with punctuation, respelling and delivery settings. In [Kveeky](https://kveeky.com/) that means the Emotion setting plus Speed and Volume.

**On this page:** [The 3-stage pipeline](#the-3-stage-pipeline) · [Is TTS AI?](#from-rules-to-neural-networks) · [How voices are made](#how-ai-voices-are-made) · [Why it sounds natural](#natural-vs-robotic-speech) · [Controlling the read](#controlling-how-a-voice-reads) · [Speech to speech](#tts-vs-speech-to-speech) · [Cloud or local](#cloud-or-local-tts) · [Quick answers](#quick-answers-on-tts-basics) · [FAQ](#frequently-asked-questions)

## The 3-stage pipeline

A text to speech engine is the software that does the whole conversion. Inside it, 3 parts hand work to each other like a relay team.

<figure role="img" aria-label="Diagram of the text to speech pipeline: your script goes to the text front end, then the acoustic model, then the vocoder, which outputs audio.">
<svg viewBox="0 0 1200 300" xmlns="http://www.w3.org/2000/svg">
<title>The text to speech pipeline</title>
<desc>Four boxes connected by arrows from left to right. Box 1, Your script. Box 2, Text front end: cleans text and turns it into phonemes. Box 3, Acoustic model: predicts a mel spectrogram with timing, pitch and stress. Box 4, Vocoder: turns the spectrogram into an audio waveform. An arrow from the vocoder points to the final audio file.</desc>
<rect x="20" y="90" width="220" height="120" rx="12" fill="#eff6ff" stroke="#1d4ed8" stroke-width="3"></rect>
<text x="130" y="140" text-anchor="middle" font-family="Inter Variable, sans-serif" font-size="26" font-weight="bold" fill="#172554">Your script</text>
<text x="130" y="175" text-anchor="middle" font-family="Inter Variable, sans-serif" font-size="18" fill="#172554">"Dr. Lee, 3 PM"</text>
<line x1="240" y1="150" x2="300" y2="150" stroke="#1d4ed8" stroke-width="4"></line>
<polygon points="300,140 318,150 300,160" fill="#1d4ed8"></polygon>
<rect x="320" y="90" width="260" height="120" rx="12" fill="#dbeafe" stroke="#1e40af" stroke-width="3"></rect>
<text x="450" y="135" text-anchor="middle" font-family="Inter Variable, sans-serif" font-size="24" font-weight="bold" fill="#172554">1. Text front end</text>
<text x="450" y="168" text-anchor="middle" font-family="Inter Variable, sans-serif" font-size="17" fill="#172554">Cleans text, finds</text>
<text x="450" y="192" text-anchor="middle" font-family="Inter Variable, sans-serif" font-size="17" fill="#172554">phonemes</text>
<line x1="580" y1="150" x2="620" y2="150" stroke="#1d4ed8" stroke-width="4"></line>
<polygon points="620,140 638,150 620,160" fill="#1d4ed8"></polygon>
<rect x="640" y="90" width="260" height="120" rx="12" stroke-width="3" style="fill:color-mix(in srgb, var(--kv-success) 12%, var(--kv-white));stroke:color-mix(in srgb, var(--kv-success) 50%, var(--kv-gray-900))"></rect>
<text x="770" y="135" text-anchor="middle" font-family="Inter Variable, sans-serif" font-size="24" font-weight="bold" style="fill:color-mix(in srgb, var(--kv-success) 50%, var(--kv-gray-900))">2. Acoustic model</text>
<text x="770" y="168" text-anchor="middle" font-family="Inter Variable, sans-serif" font-size="17" style="fill:color-mix(in srgb, var(--kv-success) 50%, var(--kv-gray-900))">Plans timing, pitch</text>
<text x="770" y="192" text-anchor="middle" font-family="Inter Variable, sans-serif" font-size="17" style="fill:color-mix(in srgb, var(--kv-success) 50%, var(--kv-gray-900))">and stress</text>
<line x1="900" y1="150" x2="940" y2="150" stroke="#1d4ed8" stroke-width="4"></line>
<polygon points="940,140 958,150 940,160" fill="#1d4ed8"></polygon>
<rect x="960" y="90" width="220" height="120" rx="12" stroke-width="3" style="fill:color-mix(in srgb, var(--kv-yellow) 16%, var(--kv-white));stroke:color-mix(in srgb, color-mix(in srgb, var(--kv-yellow) 45%, var(--kv-error)) 65%, var(--kv-gray-900))"></rect>
<text x="1070" y="135" text-anchor="middle" font-family="Inter Variable, sans-serif" font-size="24" font-weight="bold" style="fill:color-mix(in srgb, color-mix(in srgb, var(--kv-yellow) 45%, var(--kv-error)) 65%, var(--kv-gray-900))">3. Vocoder</text>
<text x="1070" y="168" text-anchor="middle" font-family="Inter Variable, sans-serif" font-size="17" style="fill:color-mix(in srgb, color-mix(in srgb, var(--kv-yellow) 45%, var(--kv-error)) 65%, var(--kv-gray-900))">Makes the audio</text>
<text x="1070" y="192" text-anchor="middle" font-family="Inter Variable, sans-serif" font-size="17" style="fill:color-mix(in srgb, color-mix(in srgb, var(--kv-yellow) 45%, var(--kv-error)) 65%, var(--kv-gray-900))">waveform</text>
<text x="600" y="265" text-anchor="middle" font-family="Inter Variable, sans-serif" font-size="20" fill="#374151">Output: an audio file you can download and edit</text>
</svg>
<figcaption>Every modern TTS engine follows this order. When a voice mispronounces a word, look at stage 1. When it sounds flat, look at stage 2. When it sounds buzzy or metallic, stage 3 is the usual cause.</figcaption>
</figure>

<div style="margin:28px 0;padding:20px 22px;background:var(--kv-blue-50);border:1px solid var(--kv-blue-100);border-radius:var(--kv-radius-md)"><div style="font:700 17px/1.3 var(--kv-font-heading);color:var(--kv-blue-950);margin-bottom:6px">Where does my problem come from? Pick a symptom</div><p style="margin:0 0 12px;font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)">The pipeline tells you which stage to look at first. Tap what you hear.</p><div style="display:flex;flex-wrap:wrap;gap:10px"><button type="button" class="tw-where-opt" data-i="0" aria-pressed="false" style="min-height:44px;padding:8px 14px;border:1px solid var(--kv-blue-700);border-radius:var(--kv-radius-sm);background:var(--kv-white);color:var(--kv-blue-700);font:600 15px/1.3 var(--kv-font-body);cursor:pointer;text-align:left">A name or brand is mispronounced</button><button type="button" class="tw-where-opt" data-i="1" aria-pressed="false" style="min-height:44px;padding:8px 14px;border:1px solid var(--kv-blue-700);border-radius:var(--kv-radius-sm);background:var(--kv-white);color:var(--kv-blue-700);font:600 15px/1.3 var(--kv-font-body);cursor:pointer;text-align:left">A number, date or abbreviation sounds wrong</button><button type="button" class="tw-where-opt" data-i="2" aria-pressed="false" style="min-height:44px;padding:8px 14px;border:1px solid var(--kv-blue-700);border-radius:var(--kv-radius-sm);background:var(--kv-white);color:var(--kv-blue-700);font:600 15px/1.3 var(--kv-font-body);cursor:pointer;text-align:left">The voice sounds flat or the stress is wrong</button><button type="button" class="tw-where-opt" data-i="3" aria-pressed="false" style="min-height:44px;padding:8px 14px;border:1px solid var(--kv-blue-700);border-radius:var(--kv-radius-sm);background:var(--kv-white);color:var(--kv-blue-700);font:600 15px/1.3 var(--kv-font-body);cursor:pointer;text-align:left">It sounds buzzy or metallic</button><button type="button" class="tw-where-opt" data-i="4" aria-pressed="false" style="min-height:44px;padding:8px 14px;border:1px solid var(--kv-blue-700);border-radius:var(--kv-radius-sm);background:var(--kv-white);color:var(--kv-blue-700);font:600 15px/1.3 var(--kv-font-body);cursor:pointer;text-align:left">Every line has the same energy</button></div><div aria-live="polite"><div class="tw-where-res" style="margin-top:12px;padding:14px 16px;background:var(--kv-white);border:1px solid var(--kv-blue-100);border-left:4px solid var(--kv-blue-700);border-radius:var(--kv-radius-sm);font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)"><strong>A name or brand is mispronounced</strong><br>Stage 1, the text front end, guessed the wrong sounds. Respell the word the way it sounds, such as "shi-VAWN" for Siobhan, then generate again.</div><div class="tw-where-res" style="margin-top:12px;padding:14px 16px;background:var(--kv-white);border:1px solid var(--kv-blue-100);border-left:4px solid var(--kv-blue-700);border-radius:var(--kv-radius-sm);font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)"><strong>A number, date or abbreviation sounds wrong</strong><br>Stage 1 again, text normalization. Write the number the way you want it read, for example as words, and expand abbreviations.</div><div class="tw-where-res" style="margin-top:12px;padding:14px 16px;background:var(--kv-white);border:1px solid var(--kv-blue-100);border-left:4px solid var(--kv-blue-700);border-radius:var(--kv-radius-sm);font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)"><strong>The voice sounds flat or the stress is wrong</strong><br>Stage 2, the acoustic model, plans timing, pitch and stress. Use punctuation for pauses, split long sentences, and pick speed and emotion to match the scene.</div><div class="tw-where-res" style="margin-top:12px;padding:14px 16px;background:var(--kv-white);border:1px solid var(--kv-blue-100);border-left:4px solid var(--kv-blue-700);border-radius:var(--kv-radius-sm);font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)"><strong>It sounds buzzy or metallic</strong><br>Stage 3, the vocoder, is the usual cause. Try a different voice, since newer vocoders sound cleaner. Text edits will not fix it.</div><div class="tw-where-res" style="margin-top:12px;padding:14px 16px;background:var(--kv-white);border:1px solid var(--kv-blue-100);border-left:4px solid var(--kv-blue-700);border-radius:var(--kv-radius-sm);font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)"><strong>Every line has the same energy</strong><br>That is a prosody problem from stage 2. Follow a long sentence with a short one, and choose an emotion that fits the scene.</div></div></div>

<script>
(function(){try{var b=document.querySelectorAll('.tw-where-opt'),r=document.querySelectorAll('.tw-where-res');if(!b.length)return;
function hide(){for(var i=0;i<r.length;i++)r[i].style.display='none';for(var j=0;j<b.length;j++){b[j].setAttribute('aria-pressed','false');b[j].style.background='var(--kv-white)';b[j].style.color='var(--kv-blue-700)'}}
hide();
for(var i=0;i<b.length;i++){b[i].addEventListener('click',function(){var n=+this.getAttribute('data-i');hide();r[n].style.display='block';this.setAttribute('aria-pressed','true');this.style.background='var(--kv-blue-700)';this.style.color='var(--kv-white)'})}}catch(e){}})();
</script>

### Stage 1: the front end reads and cleans your text

Computers don't read the way people do. The front end expands "Dr." to "Doctor," "3 PM" to "three P M" and "$9" to "nine dollars." This step is called text normalization.

It then converts words into phonemes, the small sound units of a language. The word "read" needs context here, because it sounds different in "I read it yesterday" and "I'll read it now."

<div style="margin:28px 0;padding:20px 22px;background:var(--kv-blue-50);border:1px solid var(--kv-blue-100);border-radius:var(--kv-radius-md)"><div style="font:700 17px/1.3 var(--kv-font-heading);color:var(--kv-blue-950);margin-bottom:6px">Try it: a toy text normalizer</div><p style="margin:0 0 12px;font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)">Type a line and see how a front end might expand it into spoken words. This is a simplified demo of stage 1, not a real engine, and it only handles small numbers, dollars, percentages, times and the title "Dr.".</p><label style="display:block;font:600 15px/1.4 var(--kv-font-body);color:var(--kv-gray-900)">Your text<input id="tw-in" type="text" value="Dr. Lee, 3 PM, $9, 25%" style="display:block;box-sizing:border-box;width:100%;min-height:44px;margin-top:6px;padding:0 12px;border:1px solid var(--kv-gray-300);border-radius:var(--kv-radius-sm);background:var(--kv-white);color:var(--kv-gray-900);font:400 16px/1.2 var(--kv-font-body)"></label><div id="tw-out" aria-live="polite" style="margin-top:12px;padding:14px 16px;background:var(--kv-white);border:1px solid var(--kv-blue-100);border-radius:var(--kv-radius-sm);font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)"><strong>Spoken as:</strong> Doctor Lee, three P M, nine dollars, twenty-five percent</div><p style="margin:10px 0 0;font:400 15px/1.5 var(--kv-font-body);color:var(--kv-gray-600)">Try "Room 12 opens at 9 AM" or "The year is 2026". Big numbers such as 2026 are left alone on purpose: a real engine has to decide whether that is a year or a quantity.</p></div>

<script>
(function(){try{var i=document.getElementById('tw-in'),o=document.getElementById('tw-out');if(!i||!o)return;
var ones=['zero','one','two','three','four','five','six','seven','eight','nine','ten','eleven','twelve','thirteen','fourteen','fifteen','sixteen','seventeen','eighteen','nineteen'],tens=['','','twenty','thirty','forty','fifty','sixty','seventy','eighty','ninety'];
function w(n){n=+n;if(n<20)return ones[n];if(n<100)return tens[Math.floor(n/10)]+(n%10?'-'+ones[n%10]:'');return String(n)}
function norm(s){s=s.replace(/\bDr\./g,'Doctor');
s=s.replace(/\$(\d{1,2})\b/g,function(m,n){return w(n)+(+n===1?' dollar':' dollars')});
s=s.replace(/\b(\d{1,2})\s?%/g,function(m,n){return w(n)+' percent'});
s=s.replace(/\b(\d{1,2})\s?(AM|PM|am|pm)\b/g,function(m,n,a){return w(n)+' '+a.toUpperCase().split('').join(' ')});
s=s.replace(/\b\d{1,2}\b/g,function(n){return w(n)});return s}
function u(){o.innerHTML='<strong>Spoken as:</strong> ';o.appendChild(document.createTextNode(norm(i.value)))}
i.addEventListener('input',u)}catch(e){}})();
</script>

### Stage 2: the acoustic model plans the delivery

The acoustic model is the "brain" of the system. It takes the phonemes and predicts how long each sound lasts, how high the pitch goes and which words get stress.

Most models write this plan as a **mel spectrogram**. Think of it as sheet music for speech: a picture of which frequencies are loud at each moment. For the model families that do this, such as Tacotron, FastSpeech and Transformer TTS, see our guide to the [neural network architectures behind AI voices](https://kveeky.com/blog/neural-network-voice-synthesis).

### Stage 3: the vocoder makes the sound

A spectrogram is not audio yet. The vocoder fills in the fine detail, thousands of samples per second, and outputs a waveform your speakers can play.

The vocoder has a big effect on how real a voice sounds. Older vocoders often left a buzzy, metallic edge. Our deep dive on [how neural vocoders turn spectrograms into sound](https://kveeky.com/blog/neural-vocoder-architectures) explains why newer ones sound cleaner.

## From rules to neural networks

Yes, modern text to speech is AI. Today's AI voice tools use neural networks that learn speech from recordings. Older TTS used hand-written rules or recorded fragments, which is not AI in the modern sense.

Here is how the approaches compare.

<div id="tw-filter" style="display:none;flex-wrap:wrap;gap:10px;margin:12px 0"><button type="button" class="tw-f" data-f="all" aria-pressed="true" style="min-height:44px;padding:8px 14px;border:1px solid var(--kv-blue-700);border-radius:var(--kv-radius-sm);background:var(--kv-white);color:var(--kv-blue-700);font:600 15px/1.3 var(--kv-font-body);cursor:pointer;text-align:left">Show all 4 approaches</button><button type="button" class="tw-f" data-f="ai" aria-pressed="false" style="min-height:44px;padding:8px 14px;border:1px solid var(--kv-blue-700);border-radius:var(--kv-radius-sm);background:var(--kv-white);color:var(--kv-blue-700);font:600 15px/1.3 var(--kv-font-body);cursor:pointer;text-align:left">Show only neural TTS</button></div>

<table id="tw-approaches">
<thead>
<tr><th>Approach</th><th>How it makes sound</th><th>What it sounds like</th><th>Is it AI?</th></tr>
</thead>
<tbody>
<tr><td>Formant (rule-based)</td><td>Hand-written rules shape a synthetic sound source</td><td>Clear but obviously robotic</td><td>No</td></tr>
<tr><td>Concatenative</td><td>Stitches together short clips cut from one person's recordings</td><td>Natural words, audible joins between them</td><td>Not in the modern sense</td></tr>
<tr><td>Statistical parametric</td><td>A statistical model, often a hidden Markov model, predicts speech features</td><td>Smooth but muffled and flat</td><td>Early machine learning</td></tr>
<tr><td>Neural TTS</td><td>Neural networks generate the spectrogram and the waveform</td><td>Natural rhythm and tone, few artifacts</td><td>Yes</td></tr>
</tbody>
</table>

<script>
(function(){try{var f=document.getElementById('tw-filter'),t=document.getElementById('tw-approaches');if(!f||!t)return;f.style.display='flex';var b=f.querySelectorAll('.tw-f'),r=t.querySelectorAll('tbody tr');
function set(m){for(var i=0;i<r.length;i++){var c=r[i].cells[3].textContent.trim();r[i].style.display=(m==='all'||c==='Yes')?'':'none'}
for(var j=0;j<b.length;j++){var on=b[j].getAttribute('data-f')===m;b[j].setAttribute('aria-pressed',on?'true':'false');b[j].style.background=on?'var(--kv-blue-700)':'var(--kv-white)';b[j].style.color=on?'var(--kv-white)':'var(--kv-blue-700)'}}
for(var k=0;k<b.length;k++){b[k].addEventListener('click',function(){set(this.getAttribute('data-f'))})}set('all')}catch(e){}})();
</script>

The turning point came in 2016. In the WaveNet paper, listeners rated a neural model as clearly more natural than the best older systems. That held for both English and Mandarin ([van den Oord et al., arXiv](https://arxiv.org/abs/1609.03499), retrieved 2026-10-06).

### Is text to speech generative AI?

Neural text to speech is a form of generative AI. The model doesn't search a library of recorded clips. It generates a new waveform for every script, based on patterns it learned from training audio.

Speech to text runs the other way. It also uses neural networks, but its job is recognizing words in audio, not creating new audio.

## How AI voices are made

TTS voices are made by training a neural model on recordings of a real person, matched to the text they read. Most AI voices start with many hours of scripted reading. The model learns how that speaker's voice maps from text to sound. After training, it can say sentences the speaker never recorded.

So does text to speech use real voices? Indirectly, yes. The voice is learned from a real speaker, but each sentence you generate is new audio, not a playback of a stored recording.

Multi-speaker models go further. They store each voice as a **speaker embedding**, a short list of numbers that acts like a fingerprint for timbre and accent. Switching voices then means switching fingerprints, not training a new model.

Voice cloning uses the same idea with far less audio. The VALL-E research model produced speech in an unseen speaker's voice from a 3-second recording ([Wang et al., arXiv, 2023](https://arxiv.org/abs/2301.02111), retrieved 2026-10-06). Our explainer on [zero-shot voice cloning](https://kveeky.com/blog/zero-shot-voice-cloning-ai-voiceovers) covers how that works and where it falls short.

## Natural vs robotic speech

The difference between robotic and natural speech is mostly **prosody**: rhythm, stress, pitch movement and pauses. Getting each word right isn't enough. A voice that stresses every word equally sounds like a machine, even with perfect pronunciation.

Neural models learn prosody from context. They see a whole sentence and predict that a question rises at the end, a list has small pauses, and a key word gets extra stress. That's the main reason people now ask what makes synthetic speech sound "lifelike."

Researchers measure this with listening tests. The most common is the mean opinion score (MOS), where people rate clips from 1 to 5. Tacotron 2 scored 4.53, close to the 4.58 that professionally recorded speech received ([Shen et al., arXiv](https://arxiv.org/abs/1712.05884), retrieved 2026-10-06).

A score like that comes from a lab test on one voice, not from every product. If you want to know how clarity is tested beyond MOS, read our guide on [how the intelligibility of synthetic speech is measured](https://kveeky.com/blog/synthetic-speech-intelligibility-metrics).

Neural voices still have weak spots. They can misread rare names, stress the wrong word in long sentences, or keep the same energy through a whole script. Long-form drama with big emotional shifts is still a job where a human voice actor does better.

## Controlling how a voice reads

You control a TTS voice mostly through your text. The front end and acoustic model react to every comma, spelling and line break. Small edits fix most problems, including technical jargon in training videos.

1. **Use punctuation for pauses.** A comma gives a short pause and a full stop a longer one. Break long sentences in two.
2. **Respell hard words.** If a product name or medical term comes out wrong, write it the way it sounds, such as "shi-VAWN" for the name Siobhan.
3. **Write numbers the way you want them read.** "2026" can be read as a year or a quantity. Spell it out if the voice guesses wrong.
4. **Set the delivery.** Pick speed and emotion to match the scene, then listen once before you export.

For the full script-to-audio routine, see [how to write an AI voiceover script](/blog/ai-voiceover-script) and [how to make an AI voiceover sound less robotic in 5 minutes](/blog/how-to-make-your-ai-voiceover-sound-less-robotic-in-5-minutes). If playback itself fails, use the [text-to-speech troubleshooting guide](/blog/text-to-speech-not-working-troubleshooting-guide).

<div style="margin:28px 0;padding:20px 22px;background:var(--kv-blue-50);border:1px solid var(--kv-blue-100);border-radius:var(--kv-radius-md)"><div style="font:700 17px/1.3 var(--kv-font-heading);color:var(--kv-blue-950);margin-bottom:6px">Try it: a script that tests all three stages</div><p style="margin:0 0 12px;font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)">Paste this into any voice generator, such as the free demo on the Kveeky homepage, and listen for the title, the time, the price, the name, the word "read" and the year. Then fix what went wrong with the table above.</p><div id="tw-test-text" style="padding:14px 16px;background:var(--kv-white);border:1px solid var(--kv-blue-100);border-radius:var(--kv-radius-sm);font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)">Dr. Lee will see you at 3 PM. The fee is $9. Siobhan will meet you at the desk. I read it yesterday, but I'll read it again now. The year is 2026.</div><div style="display:flex;flex-wrap:wrap;align-items:center;gap:12px;margin-top:12px"><button type="button" id="tw-test-copy" aria-live="polite" style="min-height:44px;padding:0 18px;border:0;border-radius:var(--kv-radius-sm);background:var(--kv-blue-700);color:var(--kv-white);font:600 16px/1 var(--kv-font-body);cursor:pointer" onclick="var t=document.getElementById('tw-test-text').innerText,b=this;function ok(){b.textContent='Copied';setTimeout(function(){b.textContent='Copy test script'},1800)}try{if(navigator.clipboard&&navigator.clipboard.writeText){navigator.clipboard.writeText(t).then(ok,function(){})}else{var r=document.createRange();r.selectNodeContents(document.getElementById('tw-test-text'));var s=window.getSelection();s.removeAllRanges();s.addRange(r)}}catch(e){}">Copy test script</button></div></div>

<details style="margin:16px 0;border:1px solid var(--kv-blue-100);border-radius:var(--kv-radius-md);background:var(--kv-white)"><summary style="min-height:44px;display:flex;align-items:center;padding:6px 16px;font:600 16px/1.4 var(--kv-font-body);color:var(--kv-blue-950);cursor:pointer">Show me: the same script after the fixes</summary><div style="padding:0 16px 16px;font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)"><p style="margin:0 0 8px">Round two, with the title and numbers written out and the name respelled:</p><p style="margin:0"><em>Doctor Lee will see you at three p m. The fee is nine dollars. shi-VAWN will meet you at the desk. I read it yesterday, but I'll read it again now. The year is twenty twenty-six.</em></p><p style="margin:8px 0 0">Generate both and compare. Mispronunciations that disappear were stage 1 problems.</p></div></details>

<div style="margin:28px 0;padding:18px 20px;background:var(--kv-white);border:1px solid var(--kv-blue-100);border-radius:var(--kv-radius-md)"><div style="font:700 17px/1.3 var(--kv-font-heading);color:var(--kv-blue-950);margin-bottom:6px">Listen test before you export</div><p style="margin:0 0 10px;font:400 15px/1.5 var(--kv-font-body);color:var(--kv-gray-600)">Tick each check after you play the audio once. Your ticks are saved in this browser.</p><label style="display:flex;align-items:flex-start;gap:12px;min-height:44px;padding:8px 0;font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900);cursor:pointer"><input type="checkbox" class="tw-check-chk" style="width:22px;height:22px;margin-top:2px;flex:none;accent-color:var(--kv-blue-700)"><span>Names, brands and acronyms are pronounced correctly (respelled where they were not).</span></label><label style="display:flex;align-items:flex-start;gap:12px;min-height:44px;padding:8px 0;font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900);cursor:pointer"><input type="checkbox" class="tw-check-chk" style="width:22px;height:22px;margin-top:2px;flex:none;accent-color:var(--kv-blue-700)"><span>Numbers, dates and years are read the way I meant.</span></label><label style="display:flex;align-items:flex-start;gap:12px;min-height:44px;padding:8px 0;font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900);cursor:pointer"><input type="checkbox" class="tw-check-chk" style="width:22px;height:22px;margin-top:2px;flex:none;accent-color:var(--kv-blue-700)"><span>The pauses sit where I want them, set with commas and full stops.</span></label><label style="display:flex;align-items:flex-start;gap:12px;min-height:44px;padding:8px 0;font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900);cursor:pointer"><input type="checkbox" class="tw-check-chk" style="width:22px;height:22px;margin-top:2px;flex:none;accent-color:var(--kv-blue-700)"><span>The energy changes across the script instead of staying the same.</span></label><label style="display:flex;align-items:flex-start;gap:12px;min-height:44px;padding:8px 0;font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900);cursor:pointer"><input type="checkbox" class="tw-check-chk" style="width:22px;height:22px;margin-top:2px;flex:none;accent-color:var(--kv-blue-700)"><span>I picked speed and emotion for the scene and listened again.</span></label><p id="tw-check-out" aria-live="polite" style="margin:10px 0 0;font:600 15px/1.5 var(--kv-font-body);color:var(--kv-blue-700)">Ticked: 0 of 5</p></div>

<script>
(function(){try{var b=document.querySelectorAll('.tw-check-chk'),o=document.getElementById('tw-check-out'),k='kv-tw-check';if(!o||!b.length)return;var s=[];try{s=JSON.parse(localStorage.getItem(k)||'[]')}catch(e){}
function u(){var n=0,a=[];for(var i=0;i<b.length;i++){if(b[i].checked){n++;a.push(i)}}o.textContent=n===b.length?'All 5 passed. Export it.':'Ticked: '+n+' of '+b.length;try{localStorage.setItem(k,JSON.stringify(a))}catch(e){}}
for(var i=0;i<b.length;i++){if(s.indexOf(i)>-1)b[i].checked=true;b[i].addEventListener('change',u)}u()}catch(e){}})();
</script>

Some engines also accept SSML, the Speech Synthesis Markup Language, a W3C standard. Its tags set pauses (`<break>`), pitch and rate (`<prosody>`) and stress (`<emphasis>`). Others control how numbers are read (`<say-as>`) and exact pronunciation (`<phoneme>`) ([W3C SSML 1.1](https://www.w3.org/TR/speech-synthesis11/), retrieved 2026-10-06).

<details style="margin:16px 0;border:1px solid var(--kv-blue-100);border-radius:var(--kv-radius-md);background:var(--kv-white)"><summary style="min-height:44px;display:flex;align-items:center;padding:6px 16px;font:600 16px/1.4 var(--kv-font-body);color:var(--kv-blue-950);cursor:pointer">Show me: what SSML looks like</summary><div style="padding:0 16px 16px;font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)"><p style="margin:0 0 8px">An SSML snippet for an engine that accepts it: a pause, some emphasis and a slower read. Not every tool accepts SSML, so check yours first.</p><pre style="margin:0;padding:12px 14px;overflow-x:auto;background:var(--kv-gray-50);border:1px solid var(--kv-gray-200);border-radius:var(--kv-radius-sm);font:400 14px/1.5 ui-monospace,monospace;color:var(--kv-gray-900)">&lt;speak&gt;&#10;  Welcome back. &lt;break time="500ms"/&gt;&#10;  Today's tip is &lt;emphasis&gt;short&lt;/emphasis&gt;.&#10;  &lt;prosody rate="slow"&gt;Read this part slowly.&lt;/prosody&gt;&#10;&lt;/speak&gt;</pre><p style="margin:8px 0 0">The tags are from the W3C SSML 1.1 Recommendation: <code>&lt;break&gt;</code> for pauses, <code>&lt;emphasis&gt;</code> for stress and <code>&lt;prosody&gt;</code> for rate and pitch.</p></div></details>

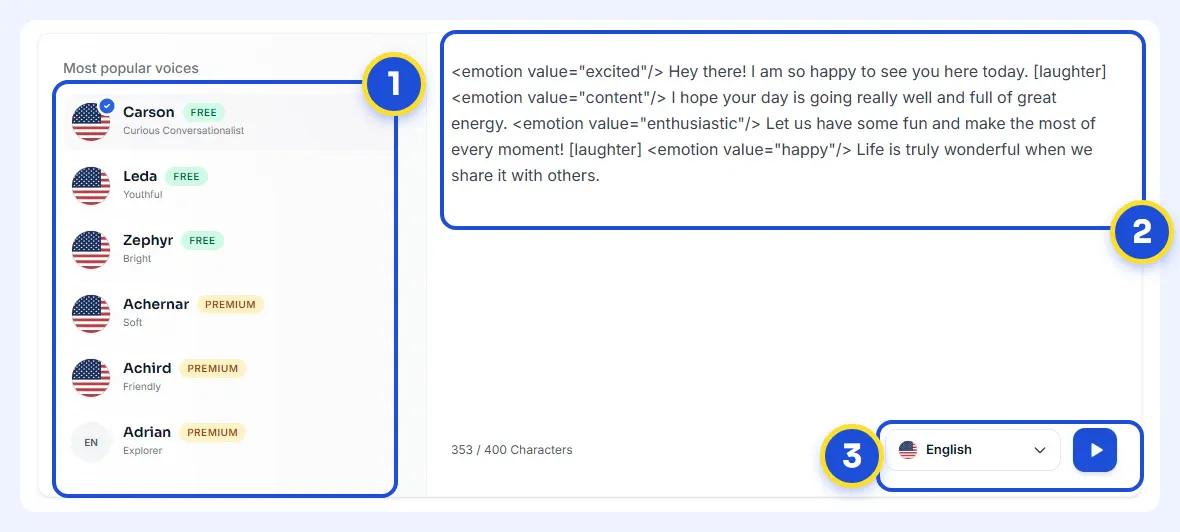
In Kveeky, you paste your script, pick from 700+ voices and adjust speed and volume. The Emotion setting offers Neutral, Happy, Love, Angry, Calm and Sad, and Custom Punctuation takes punctuation hints and word guides. You then download the audio.

<figure style="margin:28px 0;padding:0"><a href="https://kveeky.com/"><img src="https://cdn.kveeky.com/portals/public-uploads/c033eba2-39d4-4683-a5a9-c8cf2ffc6d01.webp" alt="The Kveeky homepage voice demo with three numbered areas: the voice list, the script box and the language and play controls." width="1180" height="532" loading="lazy" decoding="async" style="display:block;width:100%;height:auto;border-radius:14px;border:1px solid #dbeafe"></a><figcaption style="margin-top:12px"><ol style="margin:0;padding:0"><li style="display:flex;gap:10px;align-items:flex-start;margin:0 0 6px;padding:0;list-style:none"><span style="flex:0 0 24px;height:24px;border-radius:50%;background:#1d4ed8;color:#fff;font:700 13px/24px var(--kv-font-heading);text-align:center">1</span><span style="font:400 15px/1.5 var(--kv-font-body);color:#1f2937"><span style="font-weight:700">Pick a voice.</span> Voices are tagged Free or Premium.</span></li><li style="display:flex;gap:10px;align-items:flex-start;margin:0 0 6px;padding:0;list-style:none"><span style="flex:0 0 24px;height:24px;border-radius:50%;background:#1d4ed8;color:#fff;font:700 13px/24px var(--kv-font-heading);text-align:center">2</span><span style="font:400 15px/1.5 var(--kv-font-body);color:#1f2937"><span style="font-weight:700">Type or paste a short line.</span> Pick an emotion if you want one.</span></li><li style="display:flex;gap:10px;align-items:flex-start;margin:0 0 6px;padding:0;list-style:none"><span style="flex:0 0 24px;height:24px;border-radius:50%;background:#1d4ed8;color:#fff;font:700 13px/24px var(--kv-font-heading);text-align:center">3</span><span style="font:400 15px/1.5 var(--kv-font-body);color:#1f2937"><span style="font-weight:700">Choose the language and press play</span> to hear it.</span></li></ol><p style="margin:6px 0 0;font:400 14px/1.5 var(--kv-font-body);color:#6b7280">Try it yourself in the free voice demo on <a href="https://kveeky.com/" style="font:inherit;color:#1d4ed8">Kveeky</a>, no sign-up needed. For longer scripts and downloads, use the free plan.</p></figcaption></figure>

## TTS vs speech to speech

Text to speech starts from written words. Speech to speech starts from a recorded performance and changes the voice while keeping its timing and emotion.

Speech to speech AI works like this: a model separates what was said and how it was said from who said it. It keeps the words, pacing and feeling, then rebuilds the audio with a different voice.

It's useful when you want an exact human delivery in another voice. Our [voice style transfer guide for video producers](https://kveeky.com/blog/ai-voice-style-transfer-for-video-producers) covers it in detail.

## Cloud or local TTS

Most AI voice tools run in the cloud. You send text, a server with a GPU runs the model, and you get an audio file back. This gives you large voice libraries without any setup.

Local text to speech runs the model on your own computer. It keeps text private and works offline, but you handle installation, hardware and updates yourself. If that appeals to you, start with our overview of [open-source TTS toolkits](https://kveeky.com/blog/open-source-toolkit-for-text-to-speech-synthesis).

## Quick answers on TTS basics

These short answers cover the questions people ask most about text to speech. Each one links back to the deeper section above where it helps.

### What is text-to-speech technology?

Text-to-speech technology is software that reads written text aloud in a synthetic voice. AI voice technology is the modern form of it: neural networks trained on recorded speech that generate new audio for any script. You meet it in screen readers, navigation apps, phone menus and video voiceovers.

### Is it called text to speech, text to voice or text to audio?

They mean the same thing.

"Text to speech," shortened to TTS, is the standard technical term. "Text to voice," "text to audio" and "AI voice generator" are everyday names for the same tool. The older academic name is speech synthesis.

### What is the difference between text to speech and speech to text?

They run in opposite directions. Text to speech turns written words into audio, while speech to text, also called speech recognition or dictation, turns spoken audio into written words. To go from speech to text and back, transcribe the recording first, edit the transcript, then paste the clean text into a voice tool.

### What is the difference between an AI voice and a traditional voiceover?

A traditional voiceover is a human actor recorded in a session, while an AI voice is generated from your script in minutes. AI wins on speed, cost and easy updates, since you can fix one line without booking a studio. A human actor still wins when the performance carries the piece, such as drama, comedy or a high-stakes brand film.

### How accurate is AI text to speech?

For everyday words in well-supported languages, modern neural voices are usually accurate and easy to follow. Errors cluster around names, acronyms, numbers, rare words and languages with little training data. Free voices are often older or standard models, so test the exact voice with your hardest sentence before you rely on it.

### What are the common challenges in text-to-audio technology?

The main challenges are pronunciation of unusual words, flat delivery over long scripts, uneven quality across languages, and keeping emotion consistent. There are also misuse concerns, since the same technology can imitate real people. Most delivery problems trace back to one of the 3 pipeline stages described at the top of this guide.

### What are the advantages and disadvantages of text to speech?

The advantages are speed, low cost, consistent delivery, easy edits and access for people who can't read the screen. The disadvantages are weaker emotional range than a skilled actor, occasional mispronunciations, and a free-tier voice that may sound less natural. Some uses also need a disclosure that the voice is AI.

### What are the applications of text to speech?

Text to speech is used for accessibility tools such as screen readers, e-learning and training narration, YouTube and social video voiceovers, phone menus, audiobooks and product demos. Small teams use it most where a script changes often, because regenerating a line takes seconds. See how teams apply it to [training and onboarding narration](https://kveeky.com/voiceover/training-videos/).

### What are the latest advancements and the future of text to speech?

Recent research has focused on voice cloning from very short samples, more control over emotion and style, and single models that speak many languages. The likely next steps are better long-form delivery, more natural back-and-forth conversation, and wider use of labels or watermarks that mark audio as AI. Our [guide to neural network voice synthesis](https://kveeky.com/blog/neural-network-voice-synthesis) tracks new models with dated sources.

<!-- topic-links:start -->
## More guides

Every guide in this topic, in one place:

- [Mastering Voice Style Transfer: A Guide for Video Producers](https://kveeky.com/blog/ai-voice-style-transfer-for-video-producers)
- [Neural Network Voice Synthesis: How AI Voice Architectures Work](https://kveeky.com/blog/neural-network-voice-synthesis)
- [Neural Vocoder Architectures](https://kveeky.com/blog/neural-vocoder-architectures)
- [Open-Source Toolkit for Text-to-Speech Synthesis](https://kveeky.com/blog/open-source-toolkit-for-text-to-speech-synthesis)
- [Understanding Synthetic Speech Intelligibility Metrics for Enhanced AI Voiceovers](https://kveeky.com/blog/synthetic-speech-intelligibility-metrics)
- [Unlocking Clarity: A Video Producer's Guide to Voice Source Separation in AI Voiceover](https://kveeky.com/blog/voice-source-separation-ai-voiceover-video-production)
- [Mastering Voice User Interface (VUI) Design for AI Voiceovers](https://kveeky.com/blog/vui-design-ai-voiceovers)
- [Zero-Shot Voice Cloning: The Future of AI Voiceovers for Video Producers](https://kveeky.com/blog/zero-shot-voice-cloning-ai-voiceovers)
<!-- topic-links:end -->

## More quick answers

<details style="margin:16px 0;border:1px solid var(--kv-blue-100);border-radius:var(--kv-radius-md);background:var(--kv-white)"><summary style="min-height:44px;display:flex;align-items:center;padding:6px 16px;font:600 16px/1.4 var(--kv-font-body);color:var(--kv-blue-950);cursor:pointer">What is a vocoder in text to speech?</summary><div style="padding:0 16px 16px;font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)"><p style="margin:0">A vocoder is stage 3. It turns the spectrogram the acoustic model planned into the audio waveform your speakers play, and a good one removes the buzzy, metallic edge of older systems.</p></div></details>

<details style="margin:16px 0;border:1px solid var(--kv-blue-100);border-radius:var(--kv-radius-md);background:var(--kv-white)"><summary style="min-height:44px;display:flex;align-items:center;padding:6px 16px;font:600 16px/1.4 var(--kv-font-body);color:var(--kv-blue-950);cursor:pointer">What is text normalization?</summary><div style="padding:0 16px 16px;font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)"><p style="margin:0">It is the front end step that expands abbreviations, numbers and symbols into words, for example "Dr." to "Doctor" and "$9" to "nine dollars", before the text becomes phonemes.</p></div></details>

<details style="margin:16px 0;border:1px solid var(--kv-blue-100);border-radius:var(--kv-radius-md);background:var(--kv-white)"><summary style="min-height:44px;display:flex;align-items:center;padding:6px 16px;font:600 16px/1.4 var(--kv-font-body);color:var(--kv-blue-950);cursor:pointer">What is a mel spectrogram?</summary><div style="padding:0 16px 16px;font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)"><p style="margin:0">A picture of which frequencies are loud at each moment. Most acoustic models write their plan for the delivery in this form, like sheet music for speech.</p></div></details>

<details style="margin:16px 0;border:1px solid var(--kv-blue-100);border-radius:var(--kv-radius-md);background:var(--kv-white)"><summary style="min-height:44px;display:flex;align-items:center;padding:6px 16px;font:600 16px/1.4 var(--kv-font-body);color:var(--kv-blue-950);cursor:pointer">How much audio does voice cloning need?</summary><div style="padding:0 16px 16px;font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)"><p style="margin:0">It depends on the system. The VALL-E research model produced speech in an unseen speaker's voice from a 3-second recording. Product limits and rules differ, so check the plan you use.</p></div></details>

<details style="margin:16px 0;border:1px solid var(--kv-blue-100);border-radius:var(--kv-radius-md);background:var(--kv-white)"><summary style="min-height:44px;display:flex;align-items:center;padding:6px 16px;font:600 16px/1.4 var(--kv-font-body);color:var(--kv-blue-950);cursor:pointer">Can I try text to speech for free?</summary><div style="padding:0 16px 16px;font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)"><p style="margin:0">Yes. The free voice demo on the Kveeky homepage needs no sign-up, and the free plan gives you 500 credits a month, about 40 seconds of audio, with standard voices and no credit card.</p></div></details>

<div style="margin:28px 0;padding:18px 20px;background:var(--kv-white);border:1px solid var(--kv-blue-100);border-radius:var(--kv-radius-md)"><div style="font:700 17px/1.3 var(--kv-font-heading);color:var(--kv-blue-950);margin-bottom:8px">Keep reading</div><ul style="margin:0;padding-left:20px;font:400 16px/1.6 var(--kv-font-body);color:var(--kv-gray-900)"><li style="margin:0 0 8px"><a href="/blog/ai-voice-with-emotion" style="color:var(--kv-blue-700)">AI voice with emotion</a> - how to control emotion in AI voiceovers</li><li style="margin:0 0 8px"><a href="/blog/adding-personality-to-ai-voices-pacing-pauses-emphasis-tricks" style="color:var(--kv-blue-700)">Adding personality to AI voices</a> - pacing, pauses and emphasis</li><li style="margin:0 0 8px"><a href="/blog/google-text-to-speech" style="color:var(--kv-blue-700)">Google text to speech</a> - the built-in voices on Android, Chrome and Translate</li><li style="margin:0 0 8px"><a href="/blog/text-to-speech-vs-voice-cloning" style="color:var(--kv-blue-700)">Text to speech vs voice cloning</a> - which should you use</li><li style="margin:0 0 8px"><a href="/blog/free-vs-paid-text-to-speech" style="color:var(--kv-blue-700)">Free vs paid text to speech</a></li><li style="margin:0 0 8px"><a href="/languages/spanish-text-to-speech" style="color:var(--kv-blue-700)">Spanish text to speech</a> - one of the language pages</li><li style="margin:0 0 8px"><a href="/ai-voices" style="color:var(--kv-blue-700)">Browse AI voices</a></li><li style="margin:0 0 8px"><a href="https://kveeky.com/pricing" style="color:var(--kv-blue-700)">Kveeky pricing</a></li></ul></div>

## Frequently asked questions

### What is the difference between text to speech and speech to text?

They work in opposite directions. Text to speech turns written words into spoken audio, while speech to text, also called speech recognition, turns spoken audio into written words.

### Is text to speech AI?

Modern text to speech is AI. Today's voices are produced by neural networks trained on recorded speech. Older rule-based and concatenative systems followed fixed rules or stitched recordings together instead of learning from data.

### Is text to speech generative AI?

Neural text to speech is generative AI. The model creates a new audio waveform for each script instead of playing back stored clips. It works on the same principle as AI that generates images or text from learned patterns.

### Does text to speech use real voices?

AI voices are usually trained on recordings of real people, so the sound comes from a real speaker. The sentences you generate are new audio, though. The person never recorded those exact words.

### How does speech to speech AI work?

Speech to speech AI takes a recorded performance, keeps its words, timing and emotion, and replaces the voice with a different one. It's used for dubbing and character voices when you want a human delivery in another voice.

### Can text to speech run offline?

Yes, if you use a local model. Open-source TTS engines can run on your own computer without an internet connection. Most commercial AI voice tools generate audio on their own servers and give you a file to download.

### Why does my AI voice mispronounce some words?

The text front end guessed the wrong sounds, usually for names, brands, acronyms or jargon. Respell the word the way it sounds, add punctuation for pauses, or write numbers out in words, then generate the line again.

## How we checked this guide

This guide is written by Govind Kumar for the [Kveeky team](https://kveeky.com/). **Disclosure: Kveeky makes an AI voice generator.** We explain how TTS works in general and don't describe the internal models of any specific product, including ours.

- Research claims come from the original papers on arXiv, retrieved October 6, 2026: [WaveNet](https://arxiv.org/abs/1609.03499) (2016), [Tacotron 2](https://arxiv.org/abs/1712.05884) (2017) and [VALL-E](https://arxiv.org/abs/2301.02111) (2023).
- SSML details come from the [W3C Speech Synthesis Markup Language 1.1 Recommendation](https://www.w3.org/TR/speech-synthesis11/), retrieved October 6, 2026.
- Kveeky features and the 700+ voice count come from [kveeky.com/pricing](https://kveeky.com/pricing/), retrieved October 6, 2026.
- No Kveeky usage data is used in this guide.

Want to hear the pipeline in action? Paste a short training script with one tricky term, respell it once, and compare the two reads. Our page on [AI voiceovers for training videos](https://kveeky.com/voiceover/training-videos/) shows how teams use this for course and onboarding narration.

<p style="margin:24px 0 0;font:400 16px/1.6 var(--kv-font-body)"><strong>Related guide:</strong> <a href="/blog/from-written-words-to-natural-voiceovers-text-to-speech-workflow">From Written Words to Natural Voiceovers: A TTS Workflow</a>.</p>

<script type="application/ld+json">
{"@context":"https://schema.org","@type":"FAQPage","mainEntity":[
{"@type":"Question","name":"What is the difference between text to speech and speech to text?","acceptedAnswer":{"@type":"Answer","text":"They work in opposite directions. Text to speech turns written words into spoken audio, while speech to text, also called speech recognition, turns spoken audio into written words."}},
{"@type":"Question","name":"Is text to speech AI?","acceptedAnswer":{"@type":"Answer","text":"Modern text to speech is AI. Today's voices are produced by neural networks trained on recorded speech. Older rule-based and concatenative systems followed fixed rules or stitched recordings together instead of learning from data."}},
{"@type":"Question","name":"Is text to speech generative AI?","acceptedAnswer":{"@type":"Answer","text":"Neural text to speech is generative AI. The model creates a new audio waveform for each script instead of playing back stored clips. It works on the same principle as AI that generates images or text from learned patterns."}},
{"@type":"Question","name":"Does text to speech use real voices?","acceptedAnswer":{"@type":"Answer","text":"AI voices are usually trained on recordings of real people, so the sound comes from a real speaker. The sentences you generate are new audio, though. The person never recorded those exact words."}},
{"@type":"Question","name":"How does speech to speech AI work?","acceptedAnswer":{"@type":"Answer","text":"Speech to speech AI takes a recorded performance, keeps its words, timing and emotion, and replaces the voice with a different one. It's used for dubbing and character voices when you want a human delivery in another voice."}},
{"@type":"Question","name":"Can text to speech run offline?","acceptedAnswer":{"@type":"Answer","text":"Yes, if you use a local model. Open-source TTS engines can run on your own computer without an internet connection. Most commercial AI voice tools generate audio on their own servers and give you a file to download."}},
{"@type":"Question","name":"Why does my AI voice mispronounce some words?","acceptedAnswer":{"@type":"Answer","text":"The text front end guessed the wrong sounds, usually for names, brands, acronyms or jargon. Respell the word the way it sounds, add punctuation for pauses, or write numbers out in words, then generate the line again."}}
]}
</script>